# Facebook Posts Scraper - Page Posts, Reactions & Transcripts (`topapi/facebook-page-posts-scraper`) Actor

Scrape public Facebook Page and profile posts for $1.20 per 1,000, no start fee: text, date, reactions by type, comments, shares, views, free video transcripts, media and Page followers. Date window, monitor mode, comments add-on. Takes the input names of popular Facebook posts scrapers. No login.

- **URL**: https://apify.com/topapi/facebook-page-posts-scraper.md
- **Developed by:** [Top Api](https://apify.com/topapi) (community)
- **Categories:** Social media, Marketing, Lead generation
- **Features:** Limited permissions
- **Stats:** 43 total users, 21 monthly users, 100.0% runs succeeded, 0 bookmarks
- **User rating**: No ratings yet

## Pricing

from $1.20 / 1,000 post scrapeds

This Actor is paid per event. You are not charged for the Apify platform usage, but only a fixed price for specific events.

Learn more: https://docs.apify.com/actors/running/actors-in-store.md#pay-per-event

## What's an Apify Actor?

An Actor is a serverless cloud program that runs on the Apify platform. It has two run modes.
In Batch mode, an Actor accepts a well-defined JSON input, performs an action which can take anything from a few seconds to a few hours,
and optionally produces a well-defined JSON output, datasets with results, or files in key-value store.
In Standby mode, an Actor provides a web server which can be used as a website, API, or an MCP server.

Apify vocabulary and the platform model are defined once, in the agent quickstart at https://apify.com/agents.md.

## How to integrate an Actor?

If asked about integration, you help developers integrate Actors into their projects.
You adapt to their stack and deliver integrations that are safe, well-documented, and production-ready.

Do not guess an integration path. Every one of them is in the agent quickstart at https://apify.com/agents.md: the Apify MCP server, Agent Skills with the Apify CLI, the JavaScript and Python clients, the REST API, and the account-free path for an agent with no human to sign in. It also carries the rule on stating cost before the first paid run.

For examples already wired to this Actor's own input schema, see the [API](#api) section below.

Each client library has reference documentation the quickstart does not restate: [JavaScript/TypeScript](https://docs.apify.com/api/client/js/docs.md) (`npm install apify-client`) and [Python](https://docs.apify.com/api/client/python/docs.md) (`pip install apify-client`).

# README

### What does Facebook Page Posts Scraper do?

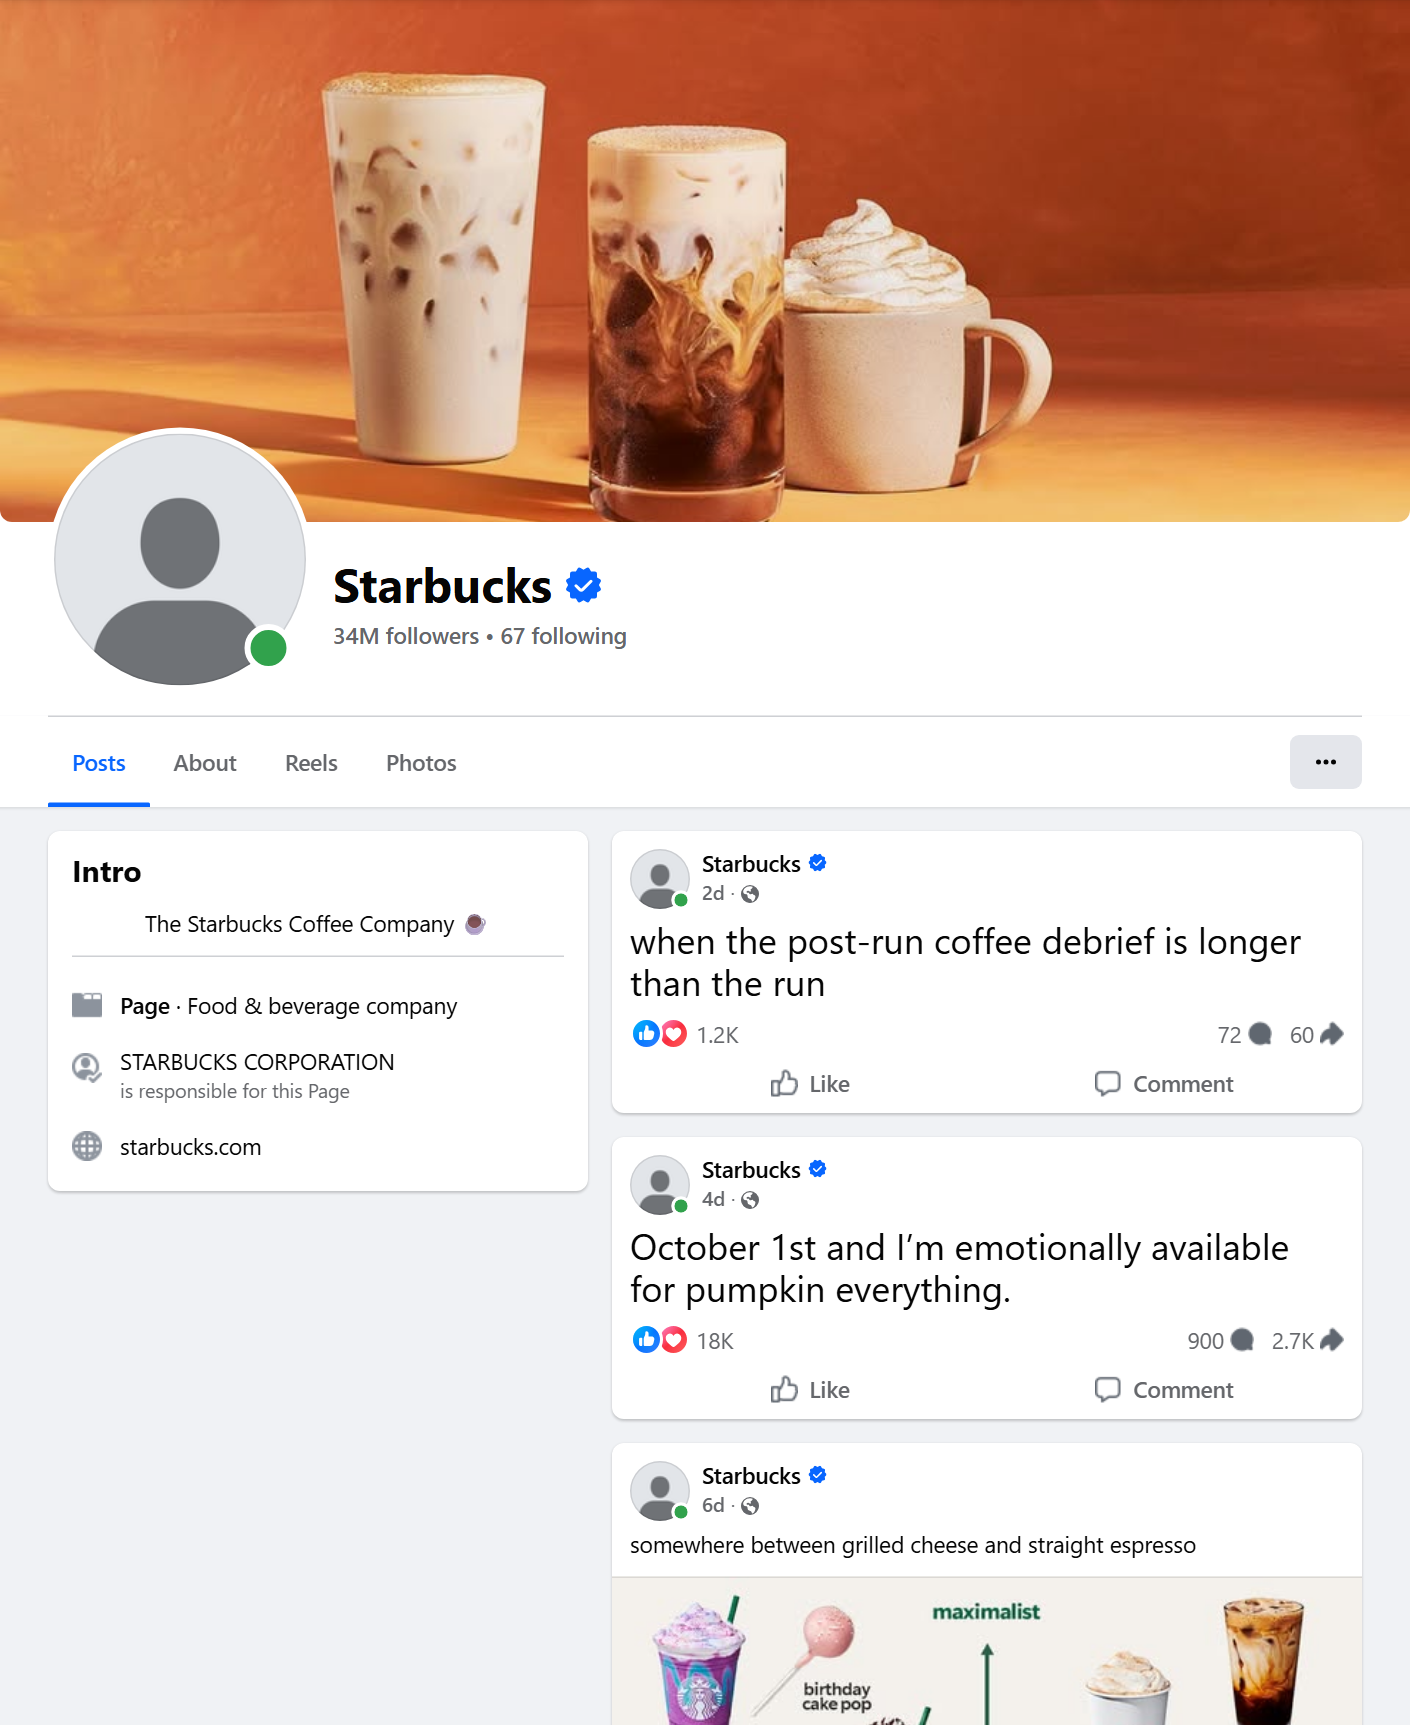
**Facebook Page Posts Scraper** collects the public posts of any Facebook Page or public profile, newest first, and turns each one into a structured row: the full text and its links, the publish date, reactions by type, comments, shares, video views and plays, photos and videos, video transcripts, a top comment, and the Page's own name, id and follower count. Give it a list of Pages and it reads each timeline the way a signed-out visitor sees it - no login, no cookies, no API key.

Facebook Posts Scraper - Facebook Page Scraper - Facebook Page Timeline API - Facebook Page Monitor

<a href="https://console.apify.com/actors/kiZdaJePboSkd43aZ"><img src="https://api.apify.com/v2/key-value-stores/qNQ9zP0xaj2yxGeMY/records/facebook-page-posts-scraper-source.png" alt="A public Facebook Page timeline that Facebook Page Posts Scraper turns into rows" style="width:70%"></a>

- **Any public Page or profile, many per run:** paste Page URLs, usernames or numeric ids; each Page is read newest post first, with Facebook's own date window - as far back as you ask (January 2024 on NASA's Page took 4 requests).
- **Every engagement number:** reactions with the like / love / care / haha / wow / sad / angry breakdown, comments, shares, video views (also the 3-second count) and plays - filled on every row of a 102-post test run.
- **Video transcripts, free:** the captions Facebook has for a video, as plain text, with every caption language it lists.
- **Comments with the details add-on:** each post's own top comments, 1-50 per post, most relevant, newest first or all - reels included - plus the video SD/HD files.
- **Page context on every row:** Page id, name, URL, followers, "talking about this" and the Page's Ad Library id, so posts from different Pages compare directly (`engagement_rate`).
- **Drop-in for other Facebook posts scrapers:** it accepts the input names of apify/facebook-posts-scraper (`resultsLimit`, `onlyPostsNewerThan`, `captionText`...), danek and scrapeforge, and can write its rows under apify's field names (`outputFormat: "apify"`).
- **Monitor mode:** remembers each Page's newest post and returns only newer ones - pair it with a schedule for a feed of new posts; a check with nothing new is not charged.
- **Export anywhere:** JSON, CSV, Excel, XML, RSS; schedules, webhooks, Make, Zapier, n8n, Google Sheets, Slack, the Apify API and MCP.

### What data can you get from a Facebook Page?

<table>
<tr>
<td>🔗 Post URL and id (`url`, `post_id`, `top_level_url`)</td>
<td>📝 Full text (`message`) and `message_rich`</td>
<td>📅 Publish date (`timestamp`, `published_at`)</td>
</tr>
<tr>
<td>📄 Page id, name, URL (`source_id`, `source_name`, `source_url`)</td>
<td>👥 Page followers, talking about, were here</td>
<td>📣 Page Ad Library id (`page_ad_library_id`)</td>
</tr>
<tr>
<td>👍 Reactions total and by type (`reactions`)</td>
<td>💬 Comments and shares (`comments_count`, `reshare_count`)</td>
<td>📈 Engagement and engagement rate</td>
</tr>
<tr>
<td>▶️ Video views, 3-second views, plays, duration, thumbnail</td>
<td>📝 Video transcript and caption tracks (`video_transcript`)</td>
<td>🖼️ Photos and albums (`image`, `images`, `image_alt`)</td>
</tr>
<tr>
<td>🌐 Outbound link and preview (`external_url`, `external_link`)</td>
<td>🔁 Shared post URL and author (`attached_post`)</td>
<td>🏷️ Hashtags, mentioned Pages, collaborators</td>
</tr>
<tr>
<td>💬 A top comment on every row</td>
<td>💬 1-50 top comments per post (details add-on)</td>
<td>🎞️ Video SD/HD files (details add-on)</td>
</tr>
</table>

On a 102-post test run (NASA, NBA, Starbucks; 34 each) every row had the date, Page followers, reactions by type, comments and shares; 47% were videos (views on 47 of 48), 13 videos carried a caption track, 83% of rows came with a top comment.

### How to scrape Facebook Page posts with Facebook Page Posts Scraper

1. [Create a free Apify account](https://console.apify.com/sign-up) - $5 of monthly credit, no card needed.
2. Open [Facebook Page Posts Scraper](https://apify.com/topapi/facebook-page-posts-scraper) and click **Try for free**.
3. Paste your Pages into **Facebook Pages** (one per line) and set **Max posts per Page**.
4. Optionally set **Posted after** / **Posted before**, a post type, minimum reactions, or switch on **Video transcripts**.
5. Click **Start**. Rows stream into the dataset as each part of each timeline arrives.
6. Open the **Storage** tab and **Export** as JSON, CSV or Excel - or let a schedule run it for you.

### ⬇️ Input

| Parameter | Type | Description |
|---|---|---|
| **🔍 What to scrape** | | |
| `startUrls` | List | **Required** (defaults to the sample Page NASA). Page URLs, usernames or numeric ids, e.g. `https://www.facebook.com/NASA`, `starbucks`, `100044561550831`; public profiles (`zuck`), `profile.php?id=` and `/people/<name>/<id>` links work too. |
| **🎯 Filters** (sent to Facebook as its timeline window) | | |
| `startDate` | String | `2026-09-01`, `2026-09-01T12:00:00Z`, `24 hours`, `7 days`, `3 weeks`, `2 months`. Facebook starts the timeline there; every post is re-checked. |
| `endDate` | String | `2026-06-30` (the whole day included) or relative, e.g. `30 days`. |
| **✂️ Refine results** (before you are charged) | | |
| `postType` | Select | `all`, `photo`, `video`, `link`, `text`, `event` or `share`. |
| `minReactions` / `minComments` / `minShares` | Integer | Keep only posts with at least this many. Default `0`. |
| `keywordFilter` | String | Keep only posts whose text, link title or event name contain a word (`sale, discount` = any). |
| `skipPostIds` | List | Post ids or URLs you already have - never delivered or charged. |
| **➕ Extra data** | | |
| `captionText` | Boolean | Free. Adds `video_transcript` (the captions file as plain text) and `video_captions` (every track) to video posts that have captions. |
| `includePostDetails` | Boolean | Adds the post's own `top_comments` and, for videos, `video_files` (SD/HD) from each post's public page - charged as **post-details** only per post that gets its own comments or files. |
| `commentsLimit` | Integer | Comments per post with details, `1`-`50`. Default `10`. |
| `commentsSort` | Select | `most_relevant` (default), `newest` or `all` - Facebook's own comment orders. |
| **🔁 Monitoring** | | |
| `monitorMode` | Boolean | Return only posts newer than the newest one already read, per Page. Pair with a schedule. Turn on `includePostDetails` later and the Page's next check also returns its last posts delivered without details (up to 12 per Page), this time with them. |
| `monitorStoreName` | String | Key-value store that keeps the per-Page memory. Default `facebook-page-posts-monitor`. |
| `resetMonitor` | Boolean | Read the Pages as on a first run once, then the memory continues. |
| **📦 Output** | | |
| `maxPostsPerPage` | Integer | Default `20`; `0` = the whole public timeline, up to 2,000 per Page. |
| `maxItems` | Integer | Hard cap for the whole run. `0` = none. |
| `outputFormat` | Select | `default` (all fields), `apify` (apify/facebook-posts-scraper field names) or `compact` (core fields for AI agents and MCP). |
| **⚙️ Advanced** | | |
| `proxyConfiguration` | Object | Residential US by default (see below). |
| `maxConcurrency` | Integer | Pages read in parallel. Default `3`, max `8`. |
| `cacheSession` | Boolean | Default on: the signed-out session is kept for up to 6 hours in the named store `facebook-page-posts-session`, so the next run skips a ~70 KB page load. For lists of 4 or more Pages the store also keeps each Page's id and header; the Page counters on a row (followers, talking about) are then at most 20 hours old, as in monitor mode. |

#### Input JSON

```json
{
  "startUrls": ["https://www.facebook.com/Starbucks", "nytimes", "https://www.facebook.com/redbull"],
  "startDate": "30 days",
  "minReactions": 100,
  "maxPostsPerPage": 50,
  "captionText": true,
  "monitorMode": false
}
```

#### Coming from another Facebook posts scraper?

Send the input you already have. These names are read as ours (when both are set, ours win unless they are left at their default):

| Their input | Read as |
|---|---|
| `startUrls: [{ "url": ... }]`, `urls`, `pageUrls`, `page_url`, `page_id` | `startUrls` |
| `resultsLimit`, `max_posts`, `postsToScrape` | `maxPostsPerPage` |
| `onlyPostsNewerThan`, `start_date`, `postsNewerThan` | `startDate` |
| `onlyPostsOlderThan`, `end_date` | `endDate` |
| `captionText`, `includeTranscripts`, `includeTranscript` | `captionText` |

With `outputFormat: "apify"` each row carries apify/facebook-posts-scraper's names - `postId`, `facebookUrl`, `pageName`, `time`, `text`, `likes`, `comments`, `shares`, `topReactionsCount`, `reaction<Type>Count`, `media[]` (with `ocrText`), `isVideo`, `viewsCount`, `videoPostViewCount`, `captionText`, `feedbackId`, `sharedPost`, `topComments`, `topLevelUrl`, `facebookId`, `pageAdLibrary`, `inputUrl` - plus `pageFollowers`, `engagementRate`, `postType` and `videoFiles`. A real row (trimmed):

```json
{
  "facebookUrl": "https://www.facebook.com/humansofnewyork/",
  "postId": "1674632237561092",
  "pageName": "humansofnewyork",
  "time": "2026-10-13T15:34:09.000Z",
  "likes": 5933,
  "comments": 196,
  "shares": 107,
  "topReactionsCount": 6,
  "reactionLikeCount": 4019,
  "reactionLoveCount": 1837,
  "isVideo": false,
  "topLevelUrl": "https://www.facebook.com/100050429952420/posts/1674632237561092",
  "facebookId": "100050429952420",
  "pageAdLibrary": { "id": "102099916530784", "is_business_page_active": false },
  "pageFollowers": 17047542
}
```

#### Give the Page itself, not a post or a group

Any address that leads to a Page or public profile works: the Page URL, its username (`redbull`), its numeric id, or a post URL of that Page (its timeline is read). For single posts by URL use [Facebook Post Details Scraper](https://apify.com/topapi/facebook-post-details-scraper). Group URLs are not Pages and are reported as invalid input, as are search, event and Watch links. A Page that does not exist or is shown only to signed-in users (some age-restricted brands) ends as `not_found` or `login_required` in the run summary and costs nothing.

#### Use the date window instead of a big cap

`startDate` and `endDate` go to Facebook as its own timeline window, so the run reads only the posts inside it: 1-31 January 2024 on NASA's Page took 4 requests to deliver 10 posts. A large `maxPostsPerPage` without a window reads the timeline from today backwards until the cap.

#### Keep the residential proxy for timelines

Facebook rate-limits Page timelines on Apify's datacenter IPs (8 of 9 requests refused on 2026-10-20), and it hides news Pages from visitors in some countries (Canada). The default residential US proxy served every timeline tested; the actor rotates to a fresh session when Facebook refuses one. Post pages for the details add-on and caption files need no residential proxy.

### ⬆️ Output

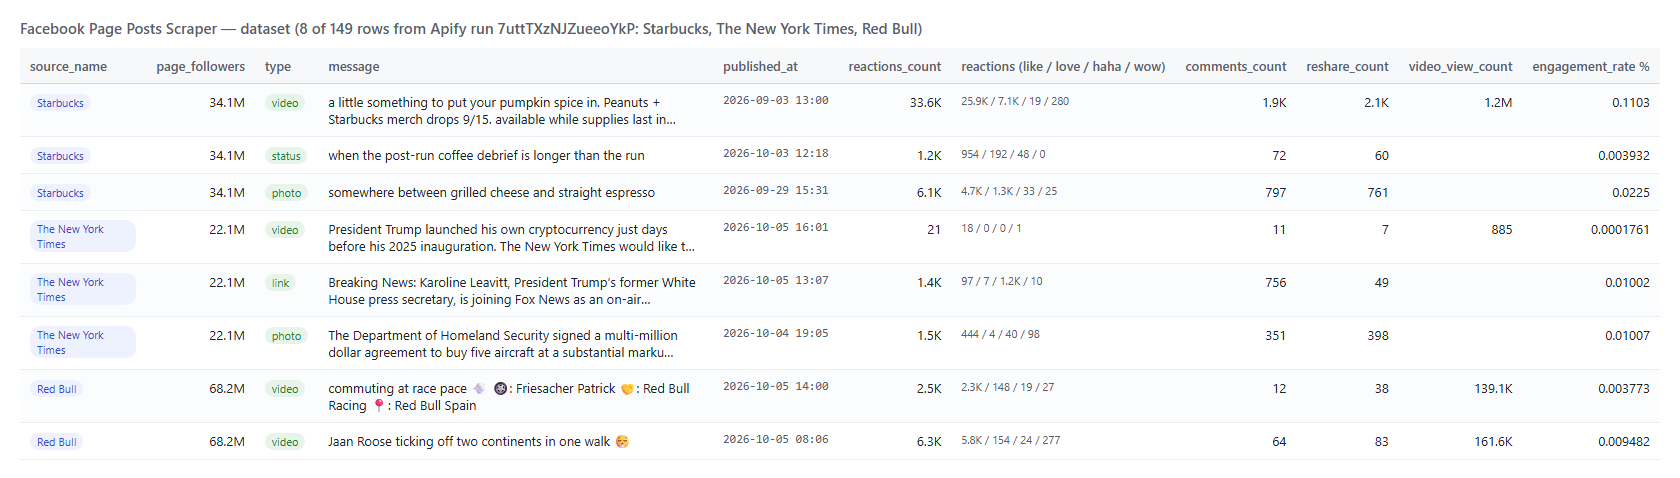
Every post becomes one dataset item. Here is the table view of a run for Starbucks, The New York Times and Red Bull:

<a href="https://console.apify.com/actors/kiZdaJePboSkd43aZ"><img src="https://api.apify.com/v2/key-value-stores/qNQ9zP0xaj2yxGeMY/records/facebook-page-posts-scraper-output.png" alt="Facebook Page Posts Scraper output table with Page posts, reactions, comments, shares and views" style="width:70%"></a>

And one real row (trimmed):

```json
{
  "post_id": "1582731997219696",
  "type": "status",
  "url": "https://www.facebook.com/Starbucks/posts/pfbid0DJSiUv3UQpCbAxHvVgqDF5pXfr882F6XX3vJdyrHgFmdBkgfRMvp5EPCmofarNDAl",
  "message": "October 1st and I’m emotionally available for pumpkin everything.",
  "published_at": "2026-10-01T11:57:25.000Z",
  "source_type": "page",
  "source_id": "100064487329582",
  "source_name": "Starbucks",
  "source_url": "https://www.facebook.com/Starbucks",
  "page_followers": 34082879,
  "page_ad_library_id": "22092443056",
  "reactions_count": 18785,
  "comments_count": 900,
  "reshare_count": 2784,
  "reactions": { "like": 12890, "love": 5377, "haha": 323, "care": 172, "wow": 12, "sad": 6, "angry": 5 },
  "engagement_count": 22469,
  "engagement_rate": 0.06592
}
```

A video row with `captionText` on (trimmed):

```json
{
  "post_id": "1662401645255205",
  "type": "video",
  "url": "https://www.facebook.com/reel/1863947697952668/",
  "video_view_count": 7129,
  "video_post_view_count": 7036,
  "video_play_count": 41339,
  "video_transcript": "Think about hundreds of square miles where we have different assets. Definitely mobility systems. ...",
  "video_captions": [{ "locale": "en_US", "language": "English", "url": "https://scontent...fbcdn.net/....srt" }]
}
```

#### Facebook Page post fields

Fill is measured on a 102-post run (NASA, NBA, Starbucks, 2026-10-20) and, for the details add-on, on a 24-post run (NASA, NBA, The New York Times).

| Field | Type | What it is | Fill |
|---|---|---|---|
| `post_id`, `url`, `story_id`, `comments_id`, `top_level_url` | string | Post id, permalink, story id, feedback id, `/<page id>/posts/<post id>` link | 100% |
| `type`, `is_video` | string, boolean | `video`, `link`, `photo`, `album`, `event`, `share`, `marketplace` or `status` | 100% |
| `message`, `message_rich` | string | Full text; the same text as HTML with its links (`message_rich` only when the text has links) | 94% / 48% |
| `timestamp`, `published_at` | integer, ISO 8601 | Publish time | 100% |
| `source_type`, `source_id`, `source_name`, `source_url`, `input_url` | string | The Page the post came from and your input line | 100% |
| `page_followers`, `page_talking_about`, `page_were_here` | integer | The Page's counters (were here = places only) | 100% / 100% / 33% |
| `page_ad_library_id`, `page_ad_library_active` | string, boolean | The Page id Meta's Ad Library uses and Facebook's business-active flag | 99% |
| `author` | object | `id`, `name`, `url`, `profile_picture_url`, `type`, `is_verified` | 100% |
| `reactions_count`, `comments_count`, `reshare_count`, `engagement_count` | integer | Totals; engagement = reactions + comments + shares | 100% |
| `reactions`, `top_reactions_count` | object, integer | `like`, `love`, `care`, `haha`, `wow`, `sad`, `angry` (an unlisted type is `0` when the listed ones add up to the total, else `null`); how many types the post shows | 100% |
| `engagement_rate` | number | Engagement as a % of the Page's followers | 100% |
| `video_view_count`, `video_post_view_count`, `video_play_count` | integer | Views, views of 3 seconds or more, plays | 47 / 45 / 45 of 48 videos |
| `video`, `video_id`, `video_thumbnail`, `video_duration_ms`, `video_is_live` | mixed | Video posts | every video post |
| `video_captions_url`, `video_captions`, `video_transcript` | string, array, string | Caption tracks and, with `captionText`, the transcript | 13 of 48 videos have captions; transcript on 2 of 2 on the details run |
| `image`, `images`, `album_count`, `image_alt` | object, array | First image, every image of an album, accessibility caption | 77% / 29% |
| `external_url`, `external_link`, `links` | string, object, array | Outbound link (unwrapped), its preview card, every link in the text | 32% / link posts / 32% |
| `attached_post_url`, `attached_post` | string, object | The original post when this one is a share | 2% |
| `event`, `location`, `collaborators` | object, array | Event posts, tagged place, co-authors | as published |
| `hashtags`, `mentions` | array | Hashtags and the Pages or profiles mentioned in the text | as published / 29% |
| `top_comment` | object | The top comment Facebook prints with the post: text, date, author, reactions | 83% |
| `top_comments`, `video_files`, `details_status` | array, object, string | The post's own comments (1-50) and its video's SD/HD files - details add-on | 24 of 24 posts: comments on 24 (reels 11 of 11), files on 11 of 11 videos |

### How can I use Facebook Page posts data?

- 📊 **Competitor benchmarking** - run your competitors' Pages weekly and compare `engagement_rate`, `reactions` by type and posting frequency.
- 📰 **Media and news monitoring** - follow publishers' Pages with `monitorMode` and get every new post, its link and its engagement.
- 🎯 **Social media reporting** - pull a client's Page for last month with `startDate` / `endDate` and chart reactions, comments, shares and views.
- 📣 **Ad and creative research** - `page_ad_library_id` takes you to the Page's ads in Meta's Ad Library; `postType: video` with `minReactions` finds the creatives that work.
- 🎙️ **Video content analysis** - `captionText` gives the spoken words of a Page's videos as text for search, summaries and topic tagging.
- 🤖 **AI and research teams** - feed `compact` rows to an LLM for summaries, topic tagging or sentiment; `top_comment` and `top_comments` add the audience's voice.

### How much does it cost to scrape Facebook Page posts?

Facebook Page Posts Scraper is pay-per-result: **$1.20 per 1,000 posts**, no start fee. You only pay for the posts you get. Video transcripts are free. The optional post details are **$1.00 per 1,000 posts** that receive their own comments or video files.

| Posts | Cost | With post details |
|---:|---:|---:|
| 10 | $0.012 | $0.022 |
| 100 | $0.12 | $0.22 |
| 1,000 | $1.20 | $2.20 |
| 10,000 | $12.00 | $22.00 |

Apify platform usage (compute and residential proxy) is included in these prices. Measured on the platform (256 MB, the default): 10 posts in about 6 seconds, 102 posts from three Pages in 25 seconds, 24 posts with details and transcripts in 47 seconds, with a peak of 43-65 MB of memory. A monitor check that finds nothing new is not charged.

### Facebook Page posts in your tools: integrations, API, scheduling & MCP

- **Schedules:** run it hourly, daily or weekly from the **Schedules** tab; with `monitorMode` each run returns only the posts published since the previous one.
- **Webhooks:** fire a URL when a run finishes - push new posts to your CRM, Slack or a sheet.
- **No-code:** Make, Zapier, n8n, Google Sheets, Airtable, Slack via [Apify integrations](https://docs.apify.com/integrations).
- **API:** call it from Node.js or Python with `apify-client` - code on the [API tab](https://apify.com/topapi/facebook-page-posts-scraper/api/python) and the [Apify API reference](https://docs.apify.com/api/v2).
- **MCP / AI agents:** connect Claude, Cursor or any MCP client through the [MCP tab](https://apify.com/topapi/facebook-page-posts-scraper/api/mcp) and ask for a Page's latest posts in plain language; set `outputFormat: "compact"` to keep rows small.

### More social media scrapers by TopApi

<table>
<tr>
<td>🔎 <a href="https://apify.com/topapi/facebook-search-posts-scraper">Facebook Search Posts Scraper</a> - public posts found by keyword, any Page or group</td>
<td>📰 <a href="https://apify.com/topapi/facebook-post-details-scraper">Facebook Post Details Scraper</a> - single posts by URL with views, shares and comments</td>
<td>💬 <a href="https://apify.com/topapi/facebook-comments-scraper">Facebook Comments Scraper</a> - every comment and reply of a post</td>
</tr>
<tr>
<td>🛒 <a href="https://apify.com/topapi/facebook-marketplace-scraper">Facebook Marketplace Scraper</a> - listings, prices and sellers by city and keyword</td>
<td>📸 <a href="https://apify.com/topapi/instagram-scraper">Instagram Scraper</a> - posts, reels, hashtags and profiles</td>
<td>🎵 <a href="https://apify.com/topapi/tiktok-scraper">TikTok Scraper</a> - videos, hashtags, profiles and search</td>
</tr>
<tr>
<td>🐦 <a href="https://apify.com/topapi/x-profile-scraper">X Profile Scraper</a> - X (Twitter) profiles and counters</td>
<td>▶️ <a href="https://apify.com/topapi/youtube-shorts-scraper">YouTube Shorts Scraper</a> - Shorts by channel, hashtag or search</td>
<td>📍 <a href="https://apify.com/topapi/google-maps-reviews-scraper">Google Maps Reviews Scraper</a> - reviews, ratings and owner replies</td>
</tr>
<tr>
<td>💼 <a href="https://apify.com/topapi/indeed-jobs-scraper">Indeed Jobs Scraper</a> - job listings with descriptions</td>
<td>🌐 <a href="https://apify.com/topapi/similarweb-scraper">Similarweb Scraper</a> - website traffic and competitors</td>
<td>🔎 <a href="https://apify.com/topapi">All TopApi actors</a> - monitor-ready scrapers for schedules, APIs and AI agents</td>
</tr>
</table>

### Limits & empty runs

- **Speed:** Facebook serves a Page timeline 3 posts per request after a first page of about 10, so a deep run takes time; several Pages run in parallel (`maxConcurrency`).
- **Depth:** up to 2,000 posts per Page per run. How far back that reaches depends on the Page: 300 NBA posts covered one week, 3 Coca-Cola posts went back to 2022. The date window is the cheaper way to reach older posts.
- **Pinned posts:** the timeline Facebook shows a signed-out visitor leaves out the Page's pinned post, so there is no pinned flag.
- **Reactions by type** are the types Facebook lists on the post; when they do not add up to the total, the unlisted types are `null`, not zero.
- **Comments:** each row carries one top comment; the details add-on adds the post's own top-level comments (1-50), not the full thread with replies - [Facebook Comments Scraper](https://apify.com/topapi/facebook-comments-scraper) does that. Facebook's comment total can lag by a few new comments. A post with no comments that is not a video gets `details_status: nothing_to_add` and the add-on is not charged; event posts have no post page (`unavailable`, not charged).
- **Transcripts** exist only for videos Facebook has captions for (13 of 48 videos on the 102-post run).
- **Not in a signed-out timeline:** paid-partnership labels, backdated original dates, call-to-action buttons and live viewer counts, so those fields are not offered.
- **Empty dataset:** the Page has no public posts in your window, every post was removed by your filters, or monitor mode found nothing new - the status message says which, and nothing is charged.
- **Not available signed-out:** private profiles, restricted-audience posts, reactor lists. Media and avatar URLs are signed CDN links that expire after a few hours.

### FAQ

#### How many posts can Facebook Page Posts Scraper collect from one Page?

Up to 2,000 per Page per run (`maxPostsPerPage: 0`), for as many Pages as you list, within the run's time limit.

#### Can I run Facebook Page Posts Scraper on a schedule to get new posts automatically?

Yes. Save your input as a task with `monitorMode: true`, open **Schedules** and pick the cadence. Each run asks Facebook only for posts newer than the newest one it already read, so a check with nothing new reads a few hundred bytes per Page, delivers nothing and is not charged. Each Page is checked about three times for every post it publishes: every 20 minutes when it posts hourly or faster, every 2 hours when it posts every 6 hours, every 8 hours when it posts daily, and at least once a day; on a faster schedule, runs in between skip it and are not charged. New posts are never lost - they are delivered by the next check. Give each feed its own `monitorStoreName`.

#### Can I scrape Facebook Page posts from a date range?

Yes. `startDate` and `endDate` accept absolute dates, timestamps or relative values such as `30 days`. The window is sent to Facebook, which starts the timeline inside it, and every post is re-checked before delivery.

#### Does Facebook Page Posts Scraper return comments?

Every row has `comments_count` and one `top_comment`. With `includePostDetails` the actor adds `top_comments` - the post's own top-level comments, 1-50 per post (`commentsLimit`), in Facebook's most relevant, newest or all order (`commentsSort`), reels included - plus `video_files` for videos.

#### Can I get video transcripts?

Yes, free: switch on `captionText`. Video posts that have captions on Facebook get `video_transcript` as plain text and `video_captions` with every caption track.

#### Can I switch from apify/facebook-posts-scraper without changing my code?

Yes. Send the same input (`startUrls`, `resultsLimit`, `onlyPostsNewerThan`, `onlyPostsOlderThan`, `captionText`) and set `outputFormat: "apify"` to get rows under the same field names.

#### Can I scrape several Facebook Pages in one run?

Yes. Put one Page per line in `startUrls`; `maxPostsPerPage` caps each Page and `maxItems` the whole run. Every row carries `source_name`, `source_url` and `input_url`, so the Pages stay apart in one dataset.

#### Can I integrate Facebook Page Posts Scraper with other apps?

Yes - Make, Zapier, n8n, Google Sheets, Slack and more via [Apify integrations](https://docs.apify.com/integrations), or use [webhooks](https://docs.apify.com/integrations/webhooks) to trigger an action when a run finishes.

#### Can I use Facebook Page Posts Scraper with the Apify API?

Yes. Use `apify-client` for [Node.js](https://apify.com/topapi/facebook-page-posts-scraper/api/javascript) or [Python](https://apify.com/topapi/facebook-page-posts-scraper/api/python); the API tab has ready-to-paste code for starting runs and fetching datasets.

#### Can I use Facebook Page Posts Scraper through an MCP server?

Yes. Open the [MCP tab](https://apify.com/topapi/facebook-page-posts-scraper/api/mcp), connect your MCP client (Claude Desktop, Cursor and others) and ask for a Page's recent posts in plain language. `outputFormat: "compact"` keeps each row to the core fields.

#### Do I need a Facebook account, cookies or an API key for Facebook Page Posts Scraper?

No. The actor reads only what Facebook shows a signed-out visitor; you pass Page addresses and nothing else. It never asks for your cookies or session.

#### Why did my Facebook Page Posts Scraper run return no results?

Most often the date window held no posts, every post was removed by a filter (the status message lists the counts), or monitor mode had nothing new. A Page that does not exist or needs a login is listed as `not_found` / `login_required` in the run summary. Changing the proxy away from residential makes Facebook refuse the timeline.

#### Is it legal to scrape Facebook Page posts?

Facebook Page Posts Scraper extracts only publicly available posts; it does not log in or collect private data. Results may still contain personal data (for example in comments and transcripts), which is regulated by laws such as GDPR. Make sure you have a legitimate purpose before you use it, and consult a lawyer if you are unsure.

#### Your feedback

We keep improving Facebook Page Posts Scraper. Found a bug or missing a field? Open an issue on the [Issues tab](https://apify.com/topapi/facebook-page-posts-scraper/issues/open).

# Actor input Schema

## `startUrls` (type: `array`):

One per line: a Page URL, a username or a numeric id, e.g. "https://www.facebook.com/NASA", "starbucks", "100044561550831". Public profiles work too ("zuck"), as do profile.php?id= and /people/<name>/<id> links. Groups are not Pages. A post URL reads its Page's timeline; for single posts use Facebook Post Details Scraper.

## `startDate` (type: `string`):

Absolute date (2026-09-01), a full timestamp (2026-09-01T12:00:00Z) or relative to now (24 hours, 7 days, 3 weeks, 2 months, 1 year). Facebook starts the timeline at this date; every post is re-checked before delivery. Empty = no lower bound. Same as onlyPostsNewerThan.

## `endDate` (type: `string`):

Absolute date (2026-06-30, the whole day included), a timestamp or relative (e.g. 30 days). Combine with 'Posted after' for a window, e.g. 2024-01-01 to 2024-01-31 (measured: 10 NASA posts from January 2024 in 4 requests). Empty = up to now. Same as onlyPostsOlderThan.

## `postType` (type: `string`):

Keep only one kind of post. On a 150-post test run (Starbucks, The New York Times, Red Bull) 48% were videos, 20% link posts, 15% photos or albums, 15% text only.

## `minReactions` (type: `integer`):

Keep only posts with at least this many reactions, e.g. 1000 for a Page's hits only. 0 = no minimum.

## `minComments` (type: `integer`):

Keep only posts with at least this many comments, e.g. 50 to find the posts people talk about. 0 = no minimum.

## `minShares` (type: `integer`):

Keep only posts shared at least this many times. 0 = no minimum.

## `keywordFilter` (type: `string`):

Keep only posts whose text, link title or event name contains this word or phrase, case-insensitive, e.g. "launch" or "sale, discount, promo" (comma = any of them). Empty = no filter.

## `skipPostIds` (type: `array`):

Post ids (or post URLs) you already have; they are never delivered or charged. Monitor mode does this for you between scheduled runs.

## `captionText` (type: `boolean`):

Adds video_transcript: the video's captions file (auto-generated or uploaded) read as plain text, plus every caption language Facebook lists. Only videos Facebook has captions for get one (12 of 27 videos on a 2026-10-20 test run). No extra charge.

## `includePostDetails` (type: `boolean`):

Opens each post's public page and adds the post's own top comments (text, author, date, reactions; reels too) and, for videos, the SD/HD file URLs. Charged as the post-details event only for posts that received their own comments or video files. Every row already carries one top comment for free.

## `commentsLimit` (type: `integer`):

How many top-level comments the details add-on returns per post, 1-50. Same price at any number.

## `commentsSort` (type: `string`):

The order Facebook's own comment menu offers.

## `monitorMode` (type: `boolean`):

Remembers, per Page, the newest post already read (in the named key-value store below) and asks Facebook only for newer ones. A scheduled check with nothing new reads a few hundred bytes per Page, delivers nothing and is not charged. Each Page is checked about three times for every post it publishes: every 20 minutes when it posts hourly or faster, every 2 hours when it posts every 6 hours, every 8 hours when it posts daily, and at least once a day; on a faster schedule, runs in between skip it and are not charged. New posts are never lost - they are delivered by the next check.

## `monitorStoreName` (type: `string`):

Name of the key-value store that keeps the per-Page memory for monitor mode. Give each separate feed (a client, a Slack channel) its own name. Letters, digits and hyphens.

## `resetMonitor` (type: `boolean`):

Ignore what the memory remembers for these Pages and read them as on a first run (the memory is then rewritten). Use once, then switch it off.

## `maxPostsPerPage` (type: `integer`):

Cap per Page after filters (your main cost control; you pay per delivered post). Facebook serves the timeline 3 posts per request after a first page of about 10. 0 = the whole public timeline, up to 2,000 per Page. Same as resultsLimit.

## `maxItems` (type: `integer`):

Hard cap for the whole run across all Pages. 0 = no total cap (each Page is still capped above).

## `outputFormat` (type: `string`):

'apify' writes the same row under the field names of apify/facebook-posts-scraper, so a pipeline built on that actor reads this one unchanged. 'Compact' keeps the core fields only.

## `compact` (type: `boolean`):

Same as Output format = compact. Kept so saved tasks keep working.

## `proxyConfiguration` (type: `object`):

Residential US by default: Facebook rate-limits the timeline on Apify's datacenter IPs (8 of 9 requests refused on 2026-10-20), and hides news Pages from some countries. The actor rotates to a fresh session when Facebook refuses one. Post pages for the details add-on go through Apify's datacenter proxy.

## `maxConcurrency` (type: `integer`):

How many Pages are read at once. 3 is a safe default; raise to 6-8 for long Page lists.

## `cacheSession` (type: `boolean`):

Keeps the signed-out session tokens (no login, no cookies of yours) in the named key-value store facebook-page-posts-session for up to 6 hours, so the next run skips a ~70 KB page load. For lists of 4 or more Pages it also keeps each Page's id and header (the followers count on a row is then at most 20 hours old). Monitor runs keep both in their monitor store. Off = every run starts fresh.

## Actor input object example

```json
{
  "startUrls": [
    "https://www.facebook.com/NASA"
  ],
  "postType": "all",
  "minReactions": 0,
  "minComments": 0,
  "minShares": 0,
  "keywordFilter": "",
  "skipPostIds": [],
  "captionText": false,
  "includePostDetails": false,
  "commentsLimit": 10,
  "commentsSort": "most_relevant",
  "monitorMode": false,
  "monitorStoreName": "facebook-page-posts-monitor",
  "resetMonitor": false,
  "maxPostsPerPage": 10,
  "maxItems": 0,
  "outputFormat": "default",
  "compact": false,
  "proxyConfiguration": {
    "useApifyProxy": true,
    "apifyProxyGroups": [
      "RESIDENTIAL"
    ],
    "apifyProxyCountry": "US"
  },
  "maxConcurrency": 3,
  "cacheSession": true
}
```

# Actor output Schema

## `posts` (type: `string`):

The dataset of Facebook Page posts (one item per post).

## `summary` (type: `string`):

Per-Page counts (read, filtered, already delivered, delivered), requests made, sessions used and bytes on the wire.

# API

You can run this Actor programmatically using our API. Below are code examples in JavaScript, Python, and CLI, as well as the OpenAPI specification and MCP server setup.

## JavaScript example

```javascript
import { ApifyClient } from 'apify-client';

// Initialize the ApifyClient with your Apify API token
// Replace the '<YOUR_API_TOKEN>' with your token
const client = new ApifyClient({
    token: '<YOUR_API_TOKEN>',
});

// Prepare Actor input
const input = {
    "startUrls": [
        "https://www.facebook.com/NASA"
    ],
    "maxPostsPerPage": 10
};

// Run the Actor and wait for it to finish
const run = await client.actor("topapi/facebook-page-posts-scraper").call(input);

// Fetch and print Actor results from the run's dataset (if any)
console.log('Results from dataset');
console.log(`💾 Check your data here: https://console.apify.com/storage/datasets/${run.defaultDatasetId}`);
const { items } = await client.dataset(run.defaultDatasetId).listItems();
items.forEach((item) => {
    console.dir(item);
});

// 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/js/docs

```

## Python example

```python
from apify_client import ApifyClient

# Initialize the ApifyClient with your Apify API token
# Replace '<YOUR_API_TOKEN>' with your token.
client = ApifyClient("<YOUR_API_TOKEN>")

# Prepare the Actor input
run_input = {
    "startUrls": ["https://www.facebook.com/NASA"],
    "maxPostsPerPage": 10,
}

# Run the Actor and wait for it to finish
run = client.actor("topapi/facebook-page-posts-scraper").call(run_input=run_input)

# Fetch and print Actor results from the run's dataset (if there are any)
print(f"💾 Check your data here: https://console.apify.com/storage/datasets/{run.default_dataset_id}")
for item in client.dataset(run.default_dataset_id).iterate_items():
    print(item)

# 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/python/docs/quick-start

```

## CLI example

```bash
echo '{
  "startUrls": [
    "https://www.facebook.com/NASA"
  ],
  "maxPostsPerPage": 10
}' |
apify call topapi/facebook-page-posts-scraper --silent --output-dataset

```

## MCP server setup

```json
{
    "mcpServers": {
        "apify": {
            "type": "http",
            "url": "https://mcp.apify.com/?tools=fetch-actor-details,topapi/facebook-page-posts-scraper"
        }
    }
}
```

The hosted server signs you in with OAuth on first connect, so no API token belongs in this config. Clients without OAuth support can send an `Authorization: Bearer <APIFY_API_TOKEN>` header instead, using a token from API & Integrations in Apify Console (https://console.apify.com/settings/integrations).

## OpenAPI specification

Download the OpenAPI definition: https://api.apify.com/v2/actors/kiZdaJePboSkd43aZ/builds/XZbx5b31plIX42wQD/openapi.json