# Facebook & Instagram Ad Library Scraper (Meta) (`thodor/meta-ad-library`) Actor
Facebook & Instagram Ad Library Scraper for commercial & e-commerce ads. Extract ad copy, videos, images, CTA & landing pages. Export to CSV or JSON. No token needed.
- **URL**: https://apify.com/thodor/meta-ad-library.md
- **Developed by:** [Thodor](https://apify.com/thodor) (community)
- **Categories:** Social media, SEO tools, Lead generation
- **Features:** Limited permissions
- **Stats:** 101 total users, 15 monthly users, 100.0% runs succeeded, 2 bookmarks
- **User rating**: No ratings yet
## Pricing
from $2.99 / 1,000 results
This Actor is paid per event. You are not charged for the Apify platform usage, but only a fixed price for specific events.
Since this Actor supports Apify Store discounts, the price gets lower the higher subscription plan you have.
Learn more: https://docs.apify.com/actors/running/actors-in-store.md#pay-per-event
## What's an Apify Actor?
An Actor is a serverless cloud program that runs on the Apify platform. It has two run modes.
In Batch mode, an Actor accepts a well-defined JSON input, performs an action which can take anything from a few seconds to a few hours,
and optionally produces a well-defined JSON output, datasets with results, or files in key-value store.
In Standby mode, an Actor provides a web server which can be used as a website, API, or an MCP server.
Apify vocabulary and the platform model are defined once, in the agent quickstart at https://apify.com/agents.md.
## How to integrate an Actor?
If asked about integration, you help developers integrate Actors into their projects.
You adapt to their stack and deliver integrations that are safe, well-documented, and production-ready.
Do not guess an integration path. Every one of them is in the agent quickstart at https://apify.com/agents.md: the Apify MCP server, Agent Skills with the Apify CLI, the JavaScript and Python clients, the REST API, and the account-free path for an agent with no human to sign in. It also carries the rule on stating cost before the first paid run.
For examples already wired to this Actor's own input schema, see the [API](#api) section below.
Each client library has reference documentation the quickstart does not restate: [JavaScript/TypeScript](https://docs.apify.com/api/client/js/docs.md) (`npm install apify-client`) and [Python](https://docs.apify.com/api/client/python/docs.md) (`pip install apify-client`).
# README
A **Facebook & Instagram Ad Library scraper tool** for every ad category, commercial ads included. Find and export ads by keyword, advertiser, or Ad Library URL, and **load them into a spreadsheet** as CSV, Excel, or JSON. Running and ended ads, with images and videos.
Outside the EU, Meta's official **Facebook Ad Library API** returns only political and social issue ads. This scraper reads Meta's public web endpoint instead: ad copy, CTA, landing page, and creative files for every ad, across Facebook, Instagram, Messenger, WhatsApp, Audience Network, and Threads. No Meta developer account, no access token.
### 📋 How to export Facebook ads to a spreadsheet
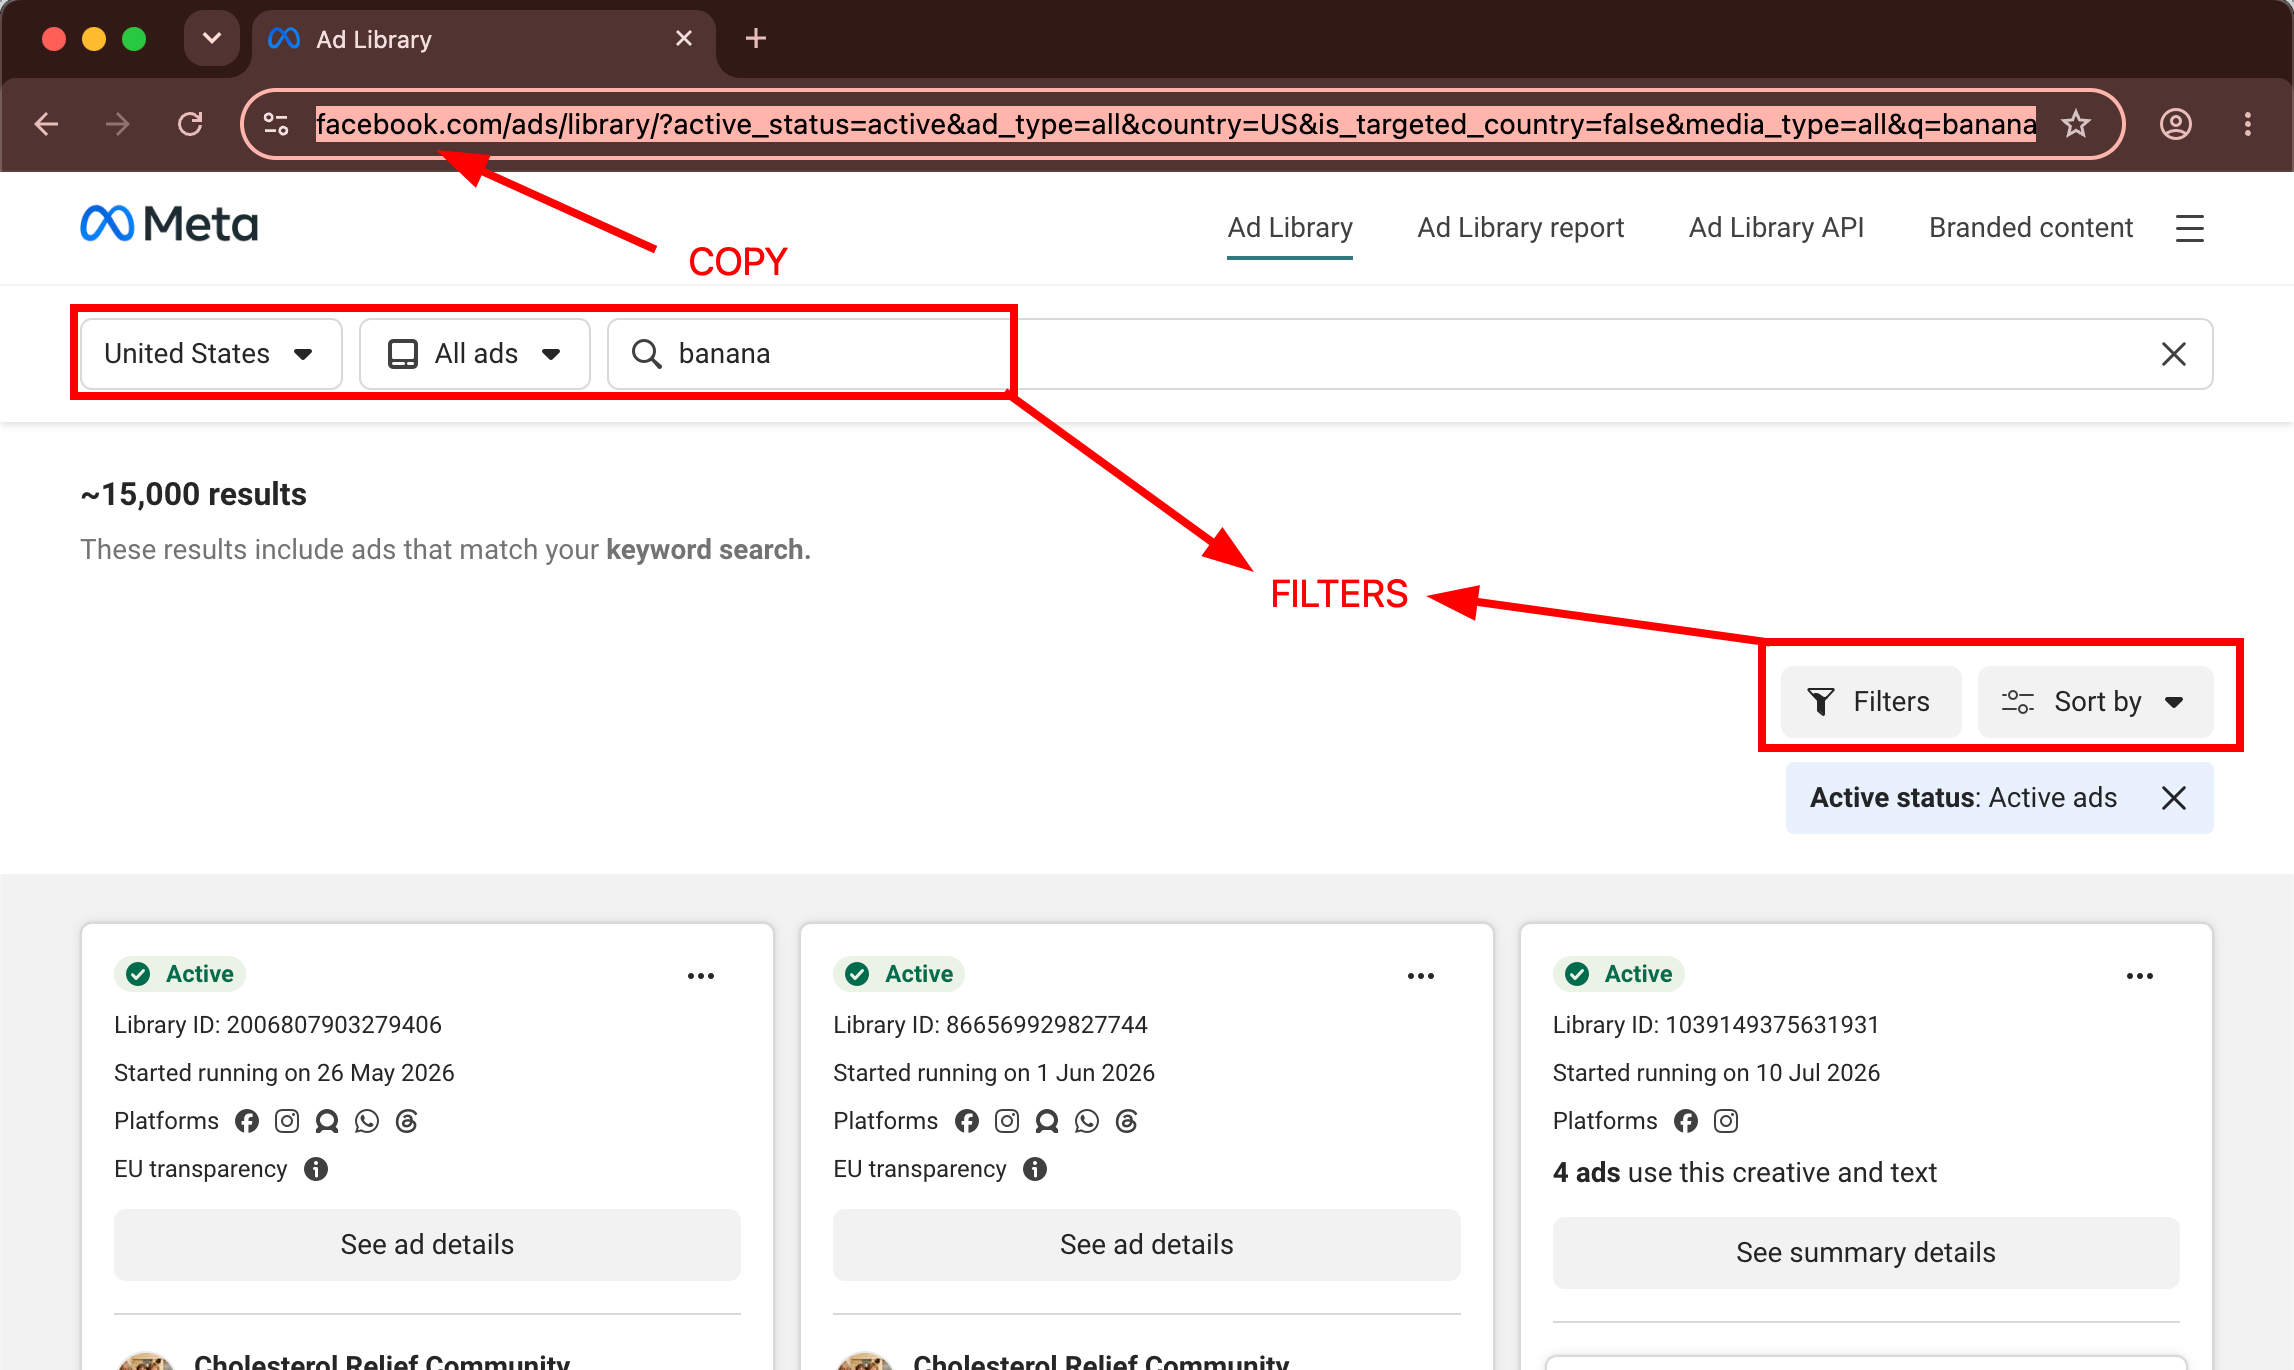
1. Open the [Facebook Ad Library](https://www.facebook.com/ads/library/) and search any keyword, e.g. [`banana`](https://www.facebook.com/ads/library/?active_status=active\&ad_type=all\&country=US\&is_targeted_country=false\&media_type=all\&q=banana\&search_type=keyword_unordered\&sort_data%5Bdirection%5D=desc\&sort_data%5Bmode%5D=total_impressions).
2. Copy the URL from the address bar after applying desired filters.
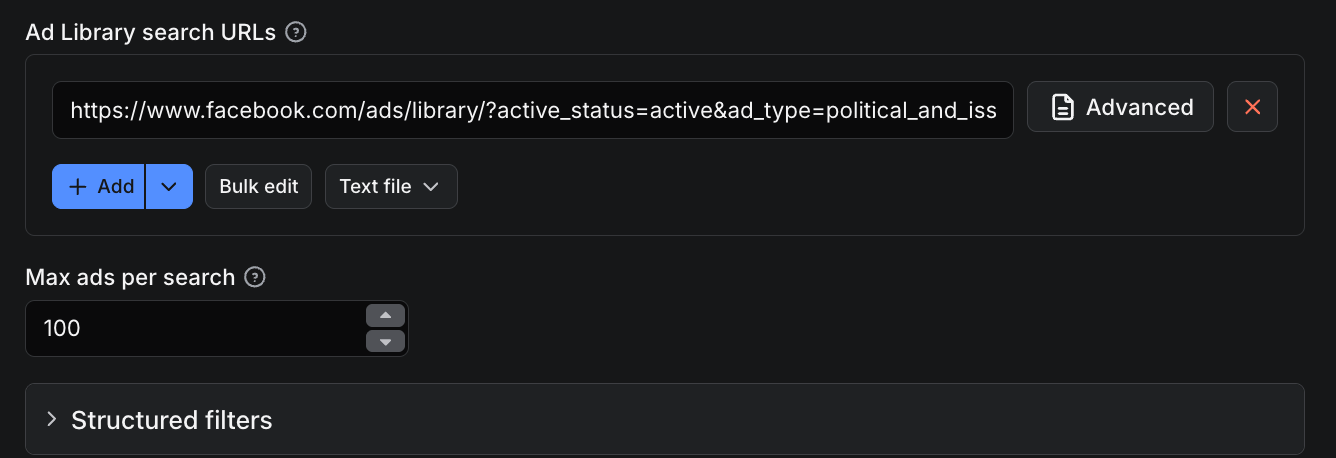
3. Paste it into **Ad Library search URLs**, replacing the prefilled example.
4. Click **Start**.
5. Open the **Output** tab and click **Export** for CSV, Excel, JSON, or HTML.
 🕵️ **Looking for a specific advertiser?**
Search the brand name and a dropdown with **Advertisers** will appear. Select the advertiser you want.
### ⚖️ Compared to Meta's official Ad Library API
| | [Meta's official API](https://www.facebook.com/ads/library/api/) | This actor |
|---|---|---|
| 🛍️ Commercial ads | ⚠️ Only ads that reached the EU | ✅ Worldwide |
| 🗳️ Political ads | ✅ | ✅ |
| 🖼️ Creative files | ❌ Snapshot page only | ✅ `image_urls`, `video_urls` |
| 🔑 Access | ❌ Gov-ID check + app review, 1 to 3 days | ✅ Register on Apify, $5 free monthly credit |
| ⏱️ Rate limits | ❌ Graph API throttling per hour | ✅ Searches run in parallel |
| 💰 Spend and reach | ⚠️ Ranges, political and EU ads | ⚠️ Ranges, political and regulated ads |
Most other scrapers only return Facebook and Instagram ads. Here every row shows which platforms the ad ran on, and you can filter to any of the six.
### 🎯 Three things people run this for
| | How |
|---|---|
| 🚀 **Catch competitor launches** | Weekly run on a [Schedule](https://docs.apify.com/platform/schedules), diff `ad_archive_id` between runs. New IDs are new creatives |
| 🔗 **Find their landing pages** | Export the `link_url` column, UTM parameters included. Feed it into the [Email Extractor](https://apify.com/thodor/apify-email-scraper-tool) for a contact list |
| 🗳️ **Track political spend** | **Ad category** political, **Active status** both. Spend, reach, and targeting, seven years back |
### 📥 Input
A pasted URL is the whole input. Set up any search at the [Facebook Ad Library](https://www.facebook.com/ads/library/), copy the URL from the address bar, and every filter you picked comes baked in. In the Console that's the entire form, paste and press **Start**. An example:
 The same input as JSON, for API calls:
```json
{
"startUrls": [
{"url": "https://www.facebook.com/ads/library/?active_status=active&ad_type=all&country=US&q=nike&search_type=keyword_unordered"}
],
"maxAdsPerSearch": 100 // 0 = unlimited
}
```
A URL isn't mandatory: every filter also exists as a plain input field, documented under **Setting filters from code** below. Three ready-to-paste inputs:
#### 🕵️ One competitor's entire ad history
Search the brand at the Ad Library, pick it under **Advertisers**, copy the URL. `active_status=all` includes ended ads, `maxAdsPerSearch: 0` removes the cap.
```json
{
"startUrls": [
{"url": "https://www.facebook.com/ads/library/?active_status=all&ad_type=all&country=ALL&view_all_page_id=933202160130540&search_type=page"}
],
"maxAdsPerSearch": 0
}
```
#### 🌍 One keyword across several countries
Three countries make three searches, and searches run in parallel.
```json
{
"searchTerms": ["running shoes"],
"countries": ["US", "GB", "DE"]
}
```
#### 🗳️ Political ads with spend and reach
The regulated categories are the only ones where Meta discloses money, see the Output section.
```json
{
"searchTerms": ["climate"],
"countries": ["US"],
"adType": "political_and_issue_ads",
"activeStatus": "all"
}
```
### 📤 Output
One flat row per ad, duplicates dropped. Results stream into the dataset while the run is going, so partial exports work immediately.
 ```json
{
"ad_archive_id": "142326985619365",
"is_active": true,
"page_id": "933202160130540",
"page_name": "Cornet Barcelona",
"page_categories": ["Product/service"],
"page_like_count": 26401,
"display_format": "VIDEO",
"is_dynamic_creative": false,
"title": "Makes The Perfect Gift",
"body_text": "If finding the perfect gift feels challenging for you...",
"caption": "www.cornetbarcelona.eu",
"cta_text": "Shop now",
"cta_type": "SHOP_NOW",
"link_url": "https://www.cornetbarcelona.eu/products/sagrada-stemless-wine-glasses",
"image_urls": [],
"video_urls": ["https://video.fbru5-1.fna.fbcdn.net/o1/v/t2/f2/m412/AQNc7ZYfS2P...&oe=6A17B41B"],
"cards": [],
"publisher_platform": ["FACEBOOK", "INSTAGRAM", "AUDIENCE_NETWORK", "MESSENGER"],
"start_date": "2023-09-18T07:00:00Z",
"end_date": null,
"currency": null,
"spend": null,
"reach_estimate": null,
"impressions_index": null,
"search_url": "https://www.facebook.com/ads/library/?..."
// HIDDEN: collation_id, collation_count, page_profile_uri, page_profile_picture_url,
// page_is_deleted, link_description, byline, categories, contains_sensitive_content,
// contains_digital_created_media, impressions_text, total_active_time,
// targeted_or_reached_countries
}
```
> ⚠️ **Media links expire in about four days.** `oe=6A17B41B` at the end of the video URL above is the expiry as hex Unix time: 2026-05-28. Download the files the day you scrape; permanent links don't exist.
> ⚠️ **Spend is null for commercial ads.** Meta only discloses finances for political and regulated ads. To find winners, sort by `start_date`: the ad above has run since 2023, and losing ads get turned off.
For a political ad, the same row carries the money fields. Trimmed to what the commercial ad above has as null:
```json
{
"ad_archive_id": "1252811692992164",
"categories": ["POLITICAL_AND_ISSUE_ADS"],
"currency": "USD",
"spend": "$600K - $700K",
"impressions_text": "1M - 2M",
"impressions_index": 1000000,
"reach_estimate": null,
"targeted_or_reached_countries": ["US"]
// HIDDEN: the same fields as the commercial ad above
}
```
#### Fields
| Field | Description |
|---|---|
| `ad_archive_id` | Meta's stable ID for this ad |
| `collation_id`, `collation_count` | Groups near-identical variants of one ad |
| `is_active` | Whether the ad is currently running |
| `page_id`, `page_name`, `page_profile_uri`, `page_profile_picture_url` | The page running the ad |
| `page_categories`, `page_like_count`, `page_is_deleted` | Page metadata |
| `display_format` | `IMAGE`, `VIDEO`, `CAROUSEL`, `DCO`, `DPA` |
| `is_dynamic_creative` | `true` when the copy holds template placeholders. Filter these out in one click |
| `title`, `body_text`, `caption`, `byline` | Ad copy |
| `cta_text`, `cta_type` | Button label and type, e.g. `SHOP_NOW` |
| `link_url`, `link_description` | Where the ad sends traffic |
| `image_urls`, `video_urls` | Signed CDN links to the creatives, see the expiry note above |
| `cards` | Per-card creative for carousel and DPA ads |
| `publisher_platform` | `FACEBOOK`, `INSTAGRAM`, `MESSENGER`, `WHATSAPP`, `AUDIENCE_NETWORK`, `THREADS` |
| `start_date`, `end_date` | ISO 8601 UTC. `end_date` is null while the ad is active |
| `total_active_time` | Seconds the ad has been running |
| `categories` | Policy categories: political, housing, credit, employment |
| `contains_sensitive_content`, `contains_digital_created_media` | Policy flags |
| `currency`, `spend`, `reach_estimate`, `impressions_text`, `impressions_index` | Regulated categories only. `spend` is a range string like `"$600K - $700K"`; `impressions_index` is the only numeric one, so sort on that |
| `targeted_or_reached_countries` | Regulated categories only, cross-border campaigns |
| `search_url` | Which input search produced this row |
### ⚙️ Setting filters from code
Every filter also exists as a plain input field under **Structured filters**. Results are identical to pasting a URL; this route saves code and automations from building URL strings. Each search term × country pair becomes one search, so 3 terms × 5 countries is 15 searches in one run.
- `searchTerms`: keywords to search instead of URLs
- `countries`: ISO codes, default `["US"]`. `["ALL"]` searches globally
- `adType`: default `all`. The regulated categories are `political_and_issue_ads`, `housing_ads`, `employment_ads`, `credit_ads`
- `activeStatus`: default `active`, or `inactive`, or `all`
- `mediaType`: default `all`, or `image`, `video`, `meme`, `image_and_meme`, `none`
- `searchType`: default `keyword_unordered`, or `keyword_exact_phrase`
- `sortBy`: default `total_impressions`, biggest spenders first. `relevancy_monthly_grouped` is newest first
- `publisherPlatforms`: default all six, or any of `facebook`, `instagram`, `messenger`, `whatsapp`, `audience_network`, `threads`. Set `["instagram"]` for Instagram-only ads, or `["threads"]` to isolate Meta's newest placement
- `startDateFrom`, `startDateTo`: `YYYY-MM-DD`
> ⚠️ Meta only supports two sorts: biggest spenders (the default) and newest. Any other sort in a pasted URL falls back to newest, and the biggest-spenders sort ignores **Start date from**. Filtering by date? Sort by newest.
> 💡 **Tip:** no need to write the JSON by hand. Configure **Structured filters** visually on the Input tab, switch the editor from **Form** to **JSON**, and copy the result into your code.
#### Python
```python
import requests
resp = requests.post(
"https://api.apify.com/v2/acts/thodor~meta-ad-library/run-sync-get-dataset-items",
params={"token": "YOUR_APIFY_TOKEN"},
json={"searchTerms": ["running shoes"], "countries": ["US"], "maxAdsPerSearch": 100},
)
for ad in resp.json():
print(ad["page_name"], ad["cta_type"], ad["link_url"])
```
#### Node.js
```javascript
import axios from "axios";
const { data } = await axios.post(
"https://api.apify.com/v2/acts/thodor~meta-ad-library/run-sync-get-dataset-items",
{ searchTerms: ["running shoes"], countries: ["US"], maxAdsPerSearch: 100 },
{ params: { token: process.env.APIFY_TOKEN } }
);
console.log(data.length, data[0].page_name, data[0].link_url);
```
#### curl
```bash
curl -X POST "https://api.apify.com/v2/acts/thodor~meta-ad-library/run-sync-get-dataset-items?token=YOUR_APIFY_TOKEN" \
-H "Content-Type: application/json" \
-d '{"searchTerms":["running shoes"],"countries":["US"],"maxAdsPerSearch":100}'
```
Swap `run-sync-get-dataset-items` for `runs` to fire async and collect results by webhook; large scrapes outlive the 5-minute sync window. The `apify-client` SDK works too, in Python and JavaScript.
### ❓ FAQ
**Why does Meta's official API hide commercial ads?**
The law forces Meta to publish political ads everywhere, and all ads that ran in the EU. Nothing forces them to publish the rest, so those only show up on the public website. This actor reads the same endpoint the website does.
**Is there a free Facebook Ad Library API?**
Meta's official API is free, but outside the EU it returns only political and social issue ads, access takes a government-ID check plus app review, and Graph API rate limits throttle bulk pulls. This actor is the alternative: call it over the Apify REST API with the same input as the form and every ad category comes back as JSON.
**Can I export Facebook ads to Excel or CSV?**
Yes. Open the **Output** tab of a run and click **Export**. CSV, Excel, JSON, JSONL, XML, and HTML, or pull the dataset over the API. Partial exports work while the run is still going.
**Can I scrape Instagram ads with this?**
Yes. Instagram ads live in the same Ad Library. Set `publisherPlatforms` to `["instagram"]` for Instagram-only results, or leave it open and filter the `publisher_platform` column afterwards. Threads works the same way.
**Can I use this Facebook Ad Library scraper for free?**
Yes. Registering on Apify comes with $5 of free platform credit every month, no credit card needed, and it runs this actor.
**Why do image and video URLs stop working?**
Every `fbcdn.net` link is signed: `oh` is the signature, `oe` the expiry, the date decoded in the Output note above. After that moment the CDN stops serving the file. An expired link can't be refreshed; scraping the ad again returns freshly signed URLs.
**Why does some ad copy read `{{product.name}}`?**
That ad is a template. Meta fills in a different product from the advertiser's catalog for every viewer, so there's no finished version to store, and every scraper gets the template. Filter them out with `is_dynamic_creative`.
**Do I need a Meta access token?**
No. Anonymous requests only. The actor handles residential proxy rotation, Chrome TLS impersonation, and Facebook's `rd_challenge` gate on its own.
**How do I make a large run faster?**
Add more searches, not a bigger one. One search stops scaling around five parallel workers because they start fetching the same ads twice; ten searches run ten times as fast.
**Is scraping the Ad Library legal?**
The Ad Library is a public transparency tool and this actor only retrieves what any logged-out visitor sees at the same URLs. Respect Meta's terms and your local law when using the data.
### 🛟 Support
Something not working, or a field missing? Message me in the Issues tab and I'll look into it quickly. I'm a solo dev, so don't hesitate.
Pairs well with the [Reverse Image Search API](https://apify.com/thodor/google-lens-exact-matches) for finding where a creative appears elsewhere, and the [CMS Detector](https://apify.com/thodor/apify-cms-detector) for profiling the landing pages you find.
- Thodor
# Actor input Schema
## `startUrls` (type: `array`):
One or more Facebook Ad Library URLs copied from your browser. Configure a search at https://www.facebook.com/ads/library/, then paste the URL here. You can add multiple URLs; each one becomes a separate search.
## `maxAdsPerSearch` (type: `integer`):
Hard cap on unique ads to collect per search (each URL or each search-term × country combination is one search). Set to 0 for no limit.
## `searchTerms` (type: `array`):
(Optional) Keywords to search for instead of (or in addition to) pasting URLs. Each term × country combination produces one search.
## `countries` (type: `array`):
ISO country codes (e.g. US, BE, DE, GB) that target ads aim at. Use 'ALL' for global. Each country produces a separate search.
## `adType` (type: `string`):
Regulated ad categories return additional fields like spend, reach, and targeting (Meta only publishes those for political/housing/employment/credit ads).
## `activeStatus` (type: `string`):
Currently running ads, or include inactive (ended) ads as well.
## `mediaType` (type: `string`):
Filter by ad creative type.
## `searchType` (type: `string`):
How the keyword is matched.
## `sortBy` (type: `string`):
Sort order for returned ads. 'Total impressions' (default) surfaces the biggest-spending competitor ads first, best for competitive intelligence. 'Most recent' surfaces newly-launched ads and is best when you set a date-range filter (it honors both ends of the range; 'Total impressions' only honors the upper bound).
## `publisherPlatforms` (type: `array`):
Filter to ads that ran on the selected Meta surfaces. Empty = all platforms.
## `startDateFrom` (type: `string`):
(Optional) Only include ads that started on or after this date. Format: YYYY-MM-DD.
## `startDateTo` (type: `string`):
(Optional) Only include ads that started on or before this date. Format: YYYY-MM-DD.
## Actor input object example
```json
{
"startUrls": [
{
"url": "https://www.facebook.com/ads/library/?active_status=active&ad_type=all&country=US&is_targeted_country=false&media_type=all&q=crypto&search_type=keyword_unordered&sort_data%5Bdirection%5D=desc&sort_data%5Bmode%5D=total_impressions"
}
],
"maxAdsPerSearch": 100,
"countries": [
"US"
],
"adType": "all",
"activeStatus": "active",
"mediaType": "all",
"searchType": "keyword_unordered",
"sortBy": "total_impressions",
"publisherPlatforms": []
}
```
# Actor output Schema
## `results` (type: `string`):
No description
# API
You can run this Actor programmatically using our API. Below are code examples in JavaScript, Python, and CLI, as well as the OpenAPI specification and MCP server setup.
## JavaScript example
```javascript
import { ApifyClient } from 'apify-client';
// Initialize the ApifyClient with your Apify API token
// Replace the '' with your token
const client = new ApifyClient({
token: '',
});
// Prepare Actor input
const input = {
"startUrls": [
{
"url": "https://www.facebook.com/ads/library/?active_status=active&ad_type=all&country=US&is_targeted_country=false&media_type=all&q=crypto&search_type=keyword_unordered&sort_data%5Bdirection%5D=desc&sort_data%5Bmode%5D=total_impressions"
}
],
"maxAdsPerSearch": 100
};
// Run the Actor and wait for it to finish
const run = await client.actor("thodor/meta-ad-library").call(input);
// Fetch and print Actor results from the run's dataset (if any)
console.log('Results from dataset');
console.log(`💾 Check your data here: https://console.apify.com/storage/datasets/${run.defaultDatasetId}`);
const { items } = await client.dataset(run.defaultDatasetId).listItems();
items.forEach((item) => {
console.dir(item);
});
// 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/js/docs
```
## Python example
```python
from apify_client import ApifyClient
# Initialize the ApifyClient with your Apify API token
# Replace '' with your token.
client = ApifyClient("")
# Prepare the Actor input
run_input = {
"startUrls": [{ "url": "https://www.facebook.com/ads/library/?active_status=active&ad_type=all&country=US&is_targeted_country=false&media_type=all&q=crypto&search_type=keyword_unordered&sort_data%5Bdirection%5D=desc&sort_data%5Bmode%5D=total_impressions" }],
"maxAdsPerSearch": 100,
}
# Run the Actor and wait for it to finish
run = client.actor("thodor/meta-ad-library").call(run_input=run_input)
# Fetch and print Actor results from the run's dataset (if there are any)
print(f"💾 Check your data here: https://console.apify.com/storage/datasets/{run.default_dataset_id}")
for item in client.dataset(run.default_dataset_id).iterate_items():
print(item)
# 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/python/docs/quick-start
```
## CLI example
```bash
echo '{
"startUrls": [
{
"url": "https://www.facebook.com/ads/library/?active_status=active&ad_type=all&country=US&is_targeted_country=false&media_type=all&q=crypto&search_type=keyword_unordered&sort_data%5Bdirection%5D=desc&sort_data%5Bmode%5D=total_impressions"
}
],
"maxAdsPerSearch": 100
}' |
apify call thodor/meta-ad-library --silent --output-dataset
```
## MCP server setup
```json
{
"mcpServers": {
"apify": {
"type": "http",
"url": "https://mcp.apify.com/?tools=fetch-actor-details,thodor/meta-ad-library"
}
}
}
```
The hosted server signs you in with OAuth on first connect, so no API token belongs in this config. Clients without OAuth support can send an `Authorization: Bearer ` header instead, using a token from API & Integrations in Apify Console (https://console.apify.com/settings/integrations).
## OpenAPI specification
Download the OpenAPI definition: https://api.apify.com/v2/actors/Hjyeuk5E4ulGOG1S5/builds/PDMZ4OYmo3JdZ2mnJ/openapi.json