# Weibo Scraper 微博 No Login \[From $2] Posts, Comments, Hot Search (`memo23/weibo-scraper`) Actor
\[From $2 per 1,000 results] Sina Weibo (微博) scraper, no login or cookie: keyword search, posts, user profiles, user posts, comments, likers, reposts, fans, following, the realtime hot search list (热搜) and rankings, plus user, topic, video and picture search. Search and user posts $3 per 1,000.
- **URL**: https://apify.com/memo23/weibo-scraper.md
- **Developed by:** [Muhamed Didovic](https://apify.com/memo23) (community)
- **Categories:** Social media, Marketing, Automation
- **Features:** Limited permissions
- **Stats:** 37 total users, 12 monthly users, 94.4% runs succeeded, 0 bookmarks
- **User rating**: No ratings yet
## Pricing
from $10.00 / 1,000 posts
This Actor is paid per event. You are not charged for the Apify platform usage, but only a fixed price for specific events.
Learn more: https://docs.apify.com/actors/running/actors-in-store.md#pay-per-event
## What's an Apify Actor?
An Actor is a serverless cloud program that runs on the Apify platform. It has two run modes.
In Batch mode, an Actor accepts a well-defined JSON input, performs an action which can take anything from a few seconds to a few hours,
and optionally produces a well-defined JSON output, datasets with results, or files in key-value store.
In Standby mode, an Actor provides a web server which can be used as a website, API, or an MCP server.
Apify vocabulary and the platform model are defined once, in the agent quickstart at https://apify.com/agents.md.
## How to integrate an Actor?
If asked about integration, you help developers integrate Actors into their projects.
You adapt to their stack and deliver integrations that are safe, well-documented, and production-ready.
Do not guess an integration path. Every one of them is in the agent quickstart at https://apify.com/agents.md: the Apify MCP server, Agent Skills with the Apify CLI, the JavaScript and Python clients, the REST API, and the account-free path for an agent with no human to sign in. It also carries the rule on stating cost before the first paid run.
For examples already wired to this Actor's own input schema, see the [API](#api) section below.
Each client library has reference documentation the quickstart does not restate: [JavaScript/TypeScript](https://docs.apify.com/api/client/js/docs.md) (`npm install apify-client`) and [Python](https://docs.apify.com/api/client/python/docs.md) (`pip install apify-client`).
# README
## Weibo Scraper 微博 — No Login: Search, Trending Posts, Profiles, Comments & Hot Search
Scrape Sina Weibo (微博) with no login, no cookie and no API key. Keyword search, trending posts (热门微博), posts, user profiles, a user's posts, comments, likers, reposts, fans, following, the realtime hot search list (热搜) and the category rankings, written to one flat dataset. **From $2 per 1,000 results**; keyword search and a user's posts cost $3 per 1,000.
An empty input searches Weibo posts for 北京. For anything else, set `operation` and the field it reads: `keyword` for the searches, `weiboId` for a post and its comments, likers or reposts, `userId` for a profile, its posts, fans or following. Each of those has a list version (`keywords`, `weiboIds`, `userIds`) for batch runs, long posts come back with their whole text, and `includeComments` adds each post's comments to the same dataset.
```json
{ "operation": "searchWeibo", "keywords": ["Tesla", "特斯拉"], "includeComments": true, "maxItems": 200 }
```
| Operation | You give | You get | Per 1,000 rows |
|---|---|---|---|
| `searchWeibo` (default) | Keyword | Posts matching the keyword | $3 |
| `hotTimeline` | Nothing | The posts trending on Weibo right now (热门微博), 10 a page | $3 |
| `hotSearch` | Nothing | The realtime 热搜 list, with rank and heat | $4 |
| `ranking` | `entertainment`, `life` or `social` | That hot list, about 50 entries | $4 |
| `weiboDetail` | Post id or URL | One post | $10 |
| `comments` | Post id or URL | Comments on the post, the first two pages (about 20) | $4 |
| `likers` | Post id or URL | Accounts that liked the post | $4 |
| `reposts` | Post id or URL | The most recent reposts, about 30 | $3 |
| `userDetail` | User id or profile URL | One profile, with follower counts | $10 |
| `userPosts` | User id or profile URL | The user's posts, newest first | $3 |
| `userFans` | User id or profile URL | Accounts that follow the user | $2 |
| `userFollowing` | User id or profile URL | Accounts the user follows | $2 |
| `advancedSearch` | Keyword | Posts with type, media and date filters | $3 |
| `searchUsers` | Keyword | Accounts, with follower counts | $2 |
| `searchTopics` | Keyword | `#topics#` with read and discussion counts | $4 |
| `searchVideos` | Keyword | Video posts, with the video file link | $3 |
| `searchPictures` | Keyword | Pictures, each with its post | $3 |
Each run also costs $0.005 to start. HTTP only, no browser, and nothing needs a login.
### Why Use This Scraper?
- Trending posts (热门微博) as full post rows, not only the hot-search words.
- Batch runs: a list of keywords, post ids or user ids in one run, one dataset.
- Whole text of long posts. Weibo's lists cut a post at about 150 characters; each cut-off post is read again, and `isTextComplete` says so on every row.
- `includeComments` puts each post's comments next to it, for search, trending posts and a user's posts.
- A user's posts with no cookie. Many Weibo actors ask for your own login cookie for that.
- Comments and likers on a public post, page by page, with no login.
- The realtime 热搜 board, with rank and heat.
- Keyword search with no login. Optional `startDay` and `endDay` drop posts outside that China calendar window.
- Post text, counts, pictures, and the author, from a mid or a `m.weibo.cn/detail` URL.
- Profile stats that the post payload leaves empty: followers, following, posts, verification.
- Fans and following of an account, with no login.
- One operation per run, so the dataset stays one shape.
### Overview
This actor reads public Sina Weibo pages for social listening, creator research, and China trend tracking. Each run does one job and writes flat rows to the Apify dataset. Export JSON, CSV, or Excel from that dataset.
A post row does not include follower counts. Those sit on the profile operation. Hot search is a live board, so the same word will not hold the same rank an hour later.
Any operation can run on a schedule from the Apify console.
The dataset is the whole result. Download it as JSON, CSV, or Excel from the run, or read it with the Apify API. Rows from different operations should not be mixed in one run, because the columns change with `_operation`. Filter on `_operation` if you merge exports later.
### Supported Inputs
Every operation runs without a login. They accept:
- `searchWeibo`: a keyword such as `北京` or `Tesla`. Optional `startDay` and `endDay` (`YYYY-MM-DD`) keep only posts whose China calendar day falls in that window. Leave both empty to keep Weibo's own ranking.
- A numeric post id (mid), for example `5249718969175092`
- A short bid, for example `QkRpSCuRm`
- `https://m.weibo.cn/detail/5249718969175092`
- `https://weibo.com/7961606632/QkRpSCuRm`
- A numeric user id, or `https://weibo.com/u/7961606632`, for the profile, the user's posts, fans and following
- Hot search needs no id
Not supported:
- Private accounts, or fan lists the account has hidden
- Comments past the first two pages, the most Weibo serves without a login
### Coming from another Weibo scraper?
| What users ask for | Where it is here |
|---|---|
| A creator's timeline without pasting a cookie | `userPosts` with only `userId`. No cookie field exists. |
| Trending posts, not just trending words | `hotTimeline`, plus `hotSearch` and `ranking` for the boards |
| Several brands or accounts in one run | `keywords`, `weiboIds`, `userIds` lists |
| Full text instead of a 150-character preview | `fetchFullText`, on by default |
| Comments on every post found | `includeComments` with `maxCommentsPerPost` |
| Fans, following, likers, reposts | Their own operations, no login |
| Promoted posts kept apart | `isAd` on every post row |
| A price you can run every day | $3 per 1,000 search or trending posts, from $2 per 1,000 rows. The best-known Weibo actor charges $35 per 1,000 items. |
### Use Cases
| Who | What they take |
|---|---|
| Brand teams | Keyword posts for several brand names in one run, with comments |
| Trend desks | Trending posts and the hot-search board on a schedule |
| Community research | Comments and likers on a post |
| Creator research | Profile stats, verification, bio |
| Agencies | A flat sheet they can hand to a client |
| Analysts | Optional China-day window on keyword search |
### How It Works
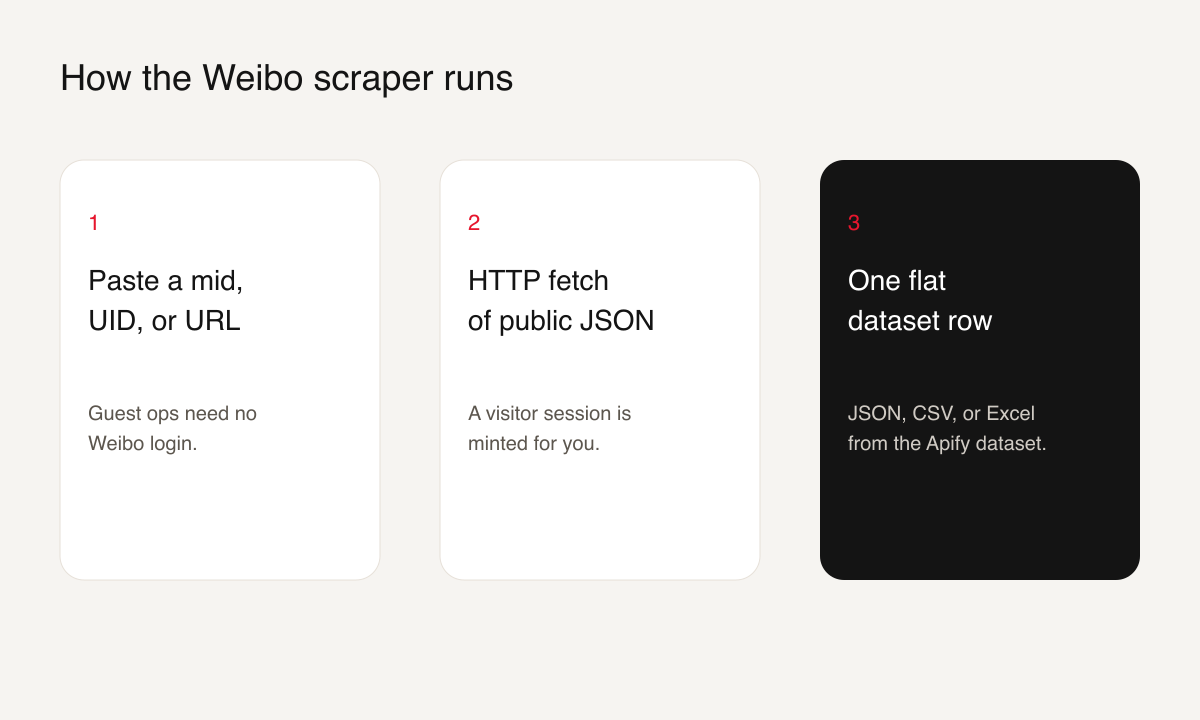
1. You pick one operation and paste the keyword, id, or URL.
2. For search, comments, likers, hot search, posts, and profiles the actor mints a visitor session and requests Weibo's public JSON. A user's posts, reposts, fans, following, rankings and the filtered, user, topic, video and picture searches come from a data source that needs no login.
3. Rows land in the dataset. `maxItems` stops the run early. `maxPages` caps search, comments, likers, fans, and following at 50 pages. A search page is about 40 posts.
### Input Configuration
| Field | Type | Required | Notes |
|---|---|---|---|
| `operation` | string | No | Default `searchWeibo`. One of `searchWeibo`, `hotTimeline`, `comments`, `likers`, `hotSearch`, `weiboDetail`, `userDetail`, `userFans`, `userFollowing`, `userPosts`, `reposts`, `advancedSearch`, `searchUsers`, `searchTopics`, `searchVideos`, `searchPictures`, `ranking`. |
| `weiboId` | string | For post, comments, likers, reposts | Mid, bid, or post URL. Prefill `5249718969175092`. No default: without it these operations fail and return no rows. |
| `userId` | string | For profile, user posts, fans, following | UID or profile URL. Prefill `1669879400`. No default: without it these operations fail and return no rows. |
| `keyword` | string | No | Used by every search operation. Default `北京`. |
| `keywords`, `weiboIds`, `userIds` | string\[] | No | Batch versions of the three fields above. When a list has entries it replaces the single field. `maxPages` applies to each entry, `maxItems` to the whole run. An entry that fails is logged and skipped. |
| `fetchFullText` | boolean | No | Default `true`. Reads the whole text of a long post. Turn off for faster runs. |
| `includeComments` | boolean | No | Default `false`. For `searchWeibo`, `hotTimeline`, `userPosts`, `weiboDetail`, `advancedSearch`, `searchVideos`: saves each post's comments as `comments` rows. |
| `maxCommentsPerPost` | integer | No | Default 20, max 100. Without a login Weibo serves about the first 2 pages. |
| `searchType` | string | No | `advancedSearch`: `all`, `hot`, `original`, `verified`, `media`, `viewpoint`. `searchVideos`: `hot` or `all`. |
| `includeType` | string | No | `advancedSearch`: `all`, `pic`, `video`, `music`, `link`. |
| `ranking` | string | No | `entertainment` (default), `life` or `social`. |
| `startDay` | string | No | `YYYY-MM-DD`. Optional search filter. No default. |
| `endDay` | string | No | `YYYY-MM-DD`. Optional search filter. No default. |
| `maxPages` | integer | No | Default 5, min 1, max 50. |
| `maxItems` | integer | No | Hard cap on rows. No default. |
| `proxy` | object | No | Leave empty to use the built-in residential proxy. |
#### Example: trending posts with their comments
```json
{
"operation": "hotTimeline",
"maxPages": 3,
"includeComments": true,
"maxCommentsPerPost": 10
}
```
#### Example: several accounts' posts
```json
{
"operation": "userPosts",
"userIds": ["1669879400", "https://weibo.com/u/1195230310"],
"maxPages": 2
}
```
#### Example: one post
```json
{
"operation": "weiboDetail",
"weiboId": "5249718969175092"
}
```
#### Example: comments, capped
```json
{
"operation": "comments",
"weiboId": "https://m.weibo.cn/detail/5249718969175092",
"maxPages": 2,
"maxItems": 50
}
```
#### Example: keyword search
```json
{
"operation": "searchWeibo",
"keyword": "北京",
"maxPages": 1,
"maxItems": 20
}
```
### Output Overview
Every row has `_operation` so you can tell which mode produced it. Post rows and search rows share the post fields. Profile, fan, and following rows share the user fields. Comment and liker rows point back at `weiboId`. Hot-search rows are a word, a rank, and a heat number.
Post rows carry `isLongText`, `isTextComplete` (true once the whole text is in `text`) and `isAd`. Comment rows added by `includeComments` have `_operation: "comments"` and `parentOperation: "includeComments"`, and point back at their post through `weiboId`.
Follower counts on a post row are often null. Run `userDetail` for that author's counts.
### Output Samples
Live rows from 21 Sep 2026. Long text and signed image URLs are shortened.
#### Post (`weiboDetail`)
```json
{
"_operation": "weiboDetail",
"weiboId": "5249718969175092",
"bid": "QkRpSCuRm",
"weiboPageUrl": "https://m.weibo.cn/detail/5249718969175092",
"text": "#檀all[超话]#\n2025.12.31 24小时文手挑战:1:00\n\n白晓宇《北京爱情故事》…",
"textLength": 3071,
"isLongText": true,
"postedAt": "Wed Dec 31 01:00:00 +0800 2025",
"repostCount": 19,
"commentCount": 36,
"attitudeCount": 169,
"regionName": "发布于 辽宁",
"source": "JCT全肯定Android",
"topics": ["檀all[超话]"],
"picCount": 1,
"screenName": "白兔猫-休养补水版",
"userId": "7961606632",
"verified": true,
"followersCount": null,
"userPageUrl": "https://weibo.com/u/7961606632"
}
```
#### Trending post (`hotTimeline`)
Live row from 20 Oct 2026, text shortened.
```json
{
"_operation": "hotTimeline",
"trendingRank": 1,
"weiboId": "5356132134556464",
"bid": "RnyfHj7lm",
"weiboPageUrl": "https://m.weibo.cn/detail/5356132134556464",
"text": "#钟南山院士才是真正的薄肌90后#钟南山院士90岁小跑开球,这身板确实让人服气。…",
"textLength": 631,
"isLongText": true,
"isTextComplete": true,
"isAd": false,
"postedAt": "Tue Oct 20 16:27:56 +0800 2026",
"repostCount": 46,
"commentCount": 49,
"attitudeCount": 160,
"regionName": "发布于 上海",
"topics": ["钟南山院士才是真正的薄肌90后"],
"picCount": 1,
"userId": "6463850400",
"screenName": "三石益友",
"verified": true,
"userPageUrl": "https://weibo.com/u/6463850400"
}
```
#### Profile (`userDetail`)
```json
{
"_operation": "userDetail",
"userId": "7961606632",
"screenName": "白兔猫-休养补水版",
"verified": true,
"verifiedReason": "娱乐博主",
"description": "做点自己爱吃的🍚",
"location": "其他",
"gender": "f",
"followersCount": 4163,
"friendsCount": 295,
"statusesCount": 6800,
"userPageUrl": "https://weibo.com/u/7961606632",
"birthday": "巨蟹座",
"createdAt": "2024-11-13 18:46:30"
}
```
#### Comment
```json
{
"_operation": "comments",
"weiboId": "5249718969175092",
"commentId": "5251110719197355",
"text": "晓宇我要在你能看见的日子里让你死死记住我的样子",
"postedAt": "01-03",
"source": "来自 辽宁",
"likeCount": 1,
"userId": "5874145289",
"screenName": "Hoo味优酸乳_家有影帝版",
"followersCount": 121,
"userPageUrl": "https://weibo.com/u/5874145289"
}
```
#### Liker
```json
{
"_operation": "likers",
"weiboId": "5249718969175092",
"attitudeId": "5331439927165740",
"postedAt": "08-13",
"source": "OPPO智能手机",
"userId": "8257425031",
"screenName": "vivi甜兔-忙碌营业版",
"followersCount": 2,
"userPageUrl": "https://weibo.com/u/8257425031"
}
```
#### Hot search
```json
{
"_operation": "hotSearch",
"rank": 1,
"word": "钟南山团队发现肺结节发病新趋势",
"hotValue": 1119668,
"label": "热",
"searchUrl": "https://s.weibo.com/weibo?q=%E9%92%9F%E5%8D%97%E5%B1%B1%E5%9B%A2%E9%98%9F%E5%8F%91%E7%8E%B0%E8%82%BA%E7%BB%93%E8%8A%82%E5%8F%91%E7%97%85%E6%96%B0%E8%B6%8B%E5%8A%BF"
}
```
### Key Output Fields
**Post, search and trending:** `weiboId`, `bid`, `text`, `isTextComplete`, `isAd`, `postedAt`, `repostCount`, `commentCount`, `attitudeCount`, `topics`, `picUrls`, `videoUrl`, `screenName`, `userId`, `keyword` (search only), `trendingRank` (trending only).
**Profile, fans, following:** `userId`, `screenName`, `verified`, `verifiedReason`, `followersCount`, `friendsCount`, `statusesCount`, `description`, `sourceUserId` (fans and following).
**Comments and likers:** `weiboId`, `commentId` or `attitudeId`, `text`, `likeCount`, `screenName`, `userId`.
**Hot search:** `rank`, `word`, `hotValue`, `label`, `searchUrl`.
### Pricing
Pay per result. Each row is charged once by its event, and each run costs $0.005 to start.
| Event | Price | When |
|---|---|---|
| `weibo-detail-result` | $0.01 | One post row |
| `user-profile-result` | $0.01 | One profile row |
| `comment-result` | $0.004 | One comment, from `comments` or added by `includeComments` |
| `liker-result` | $0.004 | One liker |
| `hot-search-result` | $0.004 | One hot-search row, one `ranking` row or one topic from `searchTopics` |
| `search-weibo-result` | $0.003 | One post row from search or trending: `searchWeibo`, `hotTimeline`, `advancedSearch`, `searchVideos`, `searchPictures`, and also `userPosts` and `reposts` |
| `user-fans-result` | $0.002 | One fan, or one account from `searchUsers` |
| `user-following-result` | $0.002 | One followed account |
A run is charged only for the rows it saves, so an empty run costs the start fee alone. Set `maxItems` when you want a ceiling.
### What makes this richer than the competition
| Capability | Typical Weibo actors | This actor |
|---|---|---|
| Trending posts as post rows | Often only the hot-search words | `hotTimeline`, no login |
| Batch keywords and ids | Often one per run | `keywords`, `weiboIds`, `userIds` |
| Whole text of long posts | Often the 150-character preview | On by default, `isTextComplete` per row |
| A user's posts | Often needs your cookie | No cookie, no login |
| Comments and likers | Often missing | Guest, no login |
| Hot-search board | Often missing | Guest, no login |
| Post and profile | Common | Guest, no login |
| Keyword search | Often bundled behind the developer's own accounts | Guest, no login |
| Fan and following lists | Same | No login |
### Notes & limitations
- Many accounts hide fans or following. The run then writes one note row instead of a list.
- Without a login Weibo serves the first two pages of comments, about 20. The run stops there and keeps those rows.
- Post detail leaves `followersCount` null. Use the profile operation.
- Hot search is live. Ranks move.
- Image URLs from Weibo can expire.
- Search dates are a filter on rows already returned, using the post's China calendar day. They do not change Weibo's ranking. A tight window can keep fewer rows than the page contains. One page is about 40 posts.
- Full text costs one extra request per long post (about one post in five). Turn `fetchFullText` off for the fastest runs.
- `hotTimeline` is Weibo's main trending feed. It does not take a keyword; use `searchWeibo` with `searchType` filters for a topic.
- Default memory is 256 MB. That is enough for these HTTP calls.
### FAQ
**Do I need a Weibo account?**
No. Every operation works without one, fans and following included.
**Does keyword search need a login?**
No. Search uses Weibo's public JSON, and the filtered, user, topic, video and picture searches come from a data source that needs no login.
**Can I scrape someone's post history?**
Yes, with `userPosts`: newest first, about 20 posts a page, up to `maxPages` pages. No cookie needed. For several accounts, pass `userIds`.
**Can I get the posts trending right now?**
Yes, `hotTimeline` returns the trending feed as post rows. `hotSearch` returns the 热搜 words with their heat.
**Why is a post's text cut off at about 150 characters on other tools?**
Weibo's lists send a preview of long posts. With `fetchFullText` on (the default) this actor reads each cut-off post again, and `isTextComplete` is true once `text` holds the whole post.
**What if the fan list is empty?**
The account hid it. Weibo lets users hide both lists; the run then writes one note row.
**Which id do I paste?**
The long number in `m.weibo.cn/detail/{id}` is the post. The number in `weibo.com/u/{id}` is the user.
### Support
Open an issue on the actor page: [memo23/weibo-scraper issues](https://apify.com/memo23/weibo-scraper/issues). Include the operation and the id or keyword you used.
### Additional Services
Need a fixed export or a schedule around a keyword list? Say what the sheet has to look like via the actor issues, or see the rest of the [memo23 actors](https://apify.com/memo23).
### Explore More Scrapers
- [Douyin Scraper](https://apify.com/memo23/douyin-scraper)
- [Xiaohongshu (RedNote) All-in-One Scraper](https://apify.com/memo23/xiaohongshu-all-in-one-scraper)
- [Bilibili Scraper](https://apify.com/memo23/bilibili-scraper)
- [All memo23 actors](https://apify.com/memo23)
### 🤖 For AI Agents & LLM Apps
Compact reference for agents calling this actor via the [Apify MCP server](https://mcp.apify.com) or the Apify API (`memo23/weibo-scraper`).
**Purpose:** Weibo trending posts, comments, likers, hot search, posts, profiles, user posts, reposts, fans, following, rankings and keyword, user, topic, video and picture search, all without a login.
**Minimal input:** `{}` searches posts for 北京. Post operations need `weiboId` and user operations need `userId`; they have no default, so a run without the id fails and returns no rows. A typical call:
```json
{ "operation": "searchWeibo", "keyword": "北京", "maxItems": 20 }
```
**Output:** one flat row per result. Post fields include `weiboId`, `bid`, `text`, `postedAt`, `repostCount`, `commentCount`, `attitudeCount`, `screenName`, `userId`. Profile fields include `followersCount`, `friendsCount`, `verifiedReason`. Hot search fields are `rank`, `word`, `hotValue`.
**Behaviors an agent should know:**
- Batch with `keywords`, `weiboIds` or `userIds` (arrays). They replace the single field when non-empty.
- `includeComments: true` adds `comments` rows after each post; `maxItems` counts them too.
- `fetchFullText` is on by default; check `isTextComplete` before treating `text` as the whole post.
- Set `maxItems`. Hot search and comments can be long. `maxPages` defaults to 5 and caps at 50.
- One operation per run (`hotTimeline` needs no field). `weiboDetail` does not fill `followersCount`. Call `userDetail` for that.
- `userFans` and `userFollowing` need only `userId`, like every other user operation. Nothing needs a login.
- Optional `startDay` / `endDay` filter search rows. They are not required.
- Field names are exact. A field the schema does not list, such as `query` or `uid`, is ignored: a search without `keyword` searches 北京.
- Pay per result: from $0.002 a row (fans, following, user search) to $0.01 (one post or profile), plus $0.005 per run.
### ⚠️ Disclaimer
This Actor is an independent tool and is not affiliated with, endorsed by, or sponsored by Weibo Corporation or any of its subsidiaries. All trademarks mentioned are the property of their respective owners.
Every operation, including keyword search, reads publicly available Weibo data without logging in. This actor does not bypass login, access private accounts, or collect passwords. You are responsible for complying with Weibo's Terms of Service, applicable data-protection law (GDPR, CCPA, and others), and your own obligations.
### SEO Keywords
weibo scraper, sina weibo scraper, 微博, 微博热搜, 热门微博, 微博爬虫, 微博评论, weibo trending posts, weibo full text, weibo batch scraper, weibo user posts no cookie, weibo hot search, weibo no login, scrape sina posts, weibo.com comments export, Apify China social, hot search board, creator profile export, fan list export, keyword date search, KOL research, brand monitoring China, liker list, post detail JSON, profile followers, public weibo dataset, China trend tracking
# Actor input Schema
## `operation` (type: `string`):
One job per run. Default searchWeibo. Nothing needs a login.
## `weiboId` (type: `string`):
Post id for weiboDetail, comments, likers and reposts. A numeric mid (example 5249718969175092), a bid such as QkRpSCuRm, or a URL such as https://m.weibo.cn/detail/5249718969175092. Required for those four operations: with no id the run fails before it returns any rows. Ignored on the other operations.
## `weiboIds` (type: `array`):
Optional. Run weiboDetail, comments, likers or reposts on several posts in one run. Same formats as the single field. When this list has entries it replaces the single field. A post that fails is logged and skipped; the run fails only when every post fails.
## `userId` (type: `string`):
User id for userDetail, userPosts, userFans and userFollowing. A numeric UID (example 1669879400) or a profile URL such as https://weibo.com/u/1669879400. Required for those four operations: with no id the run fails before it returns any rows. Prefill 1669879400 is a public account whose fans and following lists are visible. Ignored on the other operations.
## `userIds` (type: `array`):
Optional. Run userDetail, userPosts, userFans or userFollowing on several accounts in one run. Same formats as the single field. When this list has entries it replaces the single field. An account that fails is logged and skipped.
## `maxPages` (type: `integer`):
How many pages to request. Search is about 40 posts per page; filtered search, user search, picture search, user posts, fans and following about 20; video search, trending posts and comments about 10. Comments stop after 2 pages without a login. Default 5. Minimum 1. Maximum 50. Ignored for weiboDetail, userDetail, hotSearch, reposts and ranking.
## `maxItems` (type: `integer`):
Stop after this many dataset rows. Example 20. No default: comments and hot search keep going until maxPages or the end of the list. Set this on every agent run.
## `fetchFullText` (type: `boolean`):
Weibo's lists send only the first ~150 characters of a long post. When on (default), each cut-off post is read again for its whole text, and every post row says isTextComplete. Turn off for faster runs that keep the preview.
## `includeComments` (type: `boolean`):
For searchWeibo, hotTimeline, userPosts, weiboDetail, advancedSearch and searchVideos: after each post, also save its comments as rows of their own (\_operation comments, charged as comments). Up to maxCommentsPerPost per post; without a login Weibo serves about the first 2 pages.
## `maxCommentsPerPost` (type: `integer`):
With includeComments on: how many comments to save per post. Default 20.
## `keyword` (type: `string`):
Keyword for searchWeibo, advancedSearch, searchUsers, searchTopics, searchVideos and searchPictures. Chinese or English. Example 北京 or Tesla. Default 北京. Use the Several keywords list below for more than one. Ignored on the other operations.
## `keywords` (type: `array`):
Optional. Search several keywords in one run, one after another into the same dataset (each row keeps its keyword). When this list has entries it replaces the single keyword field. maxPages applies to each keyword, maxItems to the whole run.
## `startDay` (type: `string`):
Optional. Keep search posts whose China calendar day is on or after this YYYY-MM-DD. Example 2026-08-22. Leave empty to keep Weibo's own ranking. Used by searchWeibo and advancedSearch (which needs both start and end date).
## `endDay` (type: `string`):
Optional. Keep search posts whose China calendar day is on or before this YYYY-MM-DD. Example 2026-09-21. Leave empty for no end cap. Ignored unless operation is searchWeibo.
## `searchType` (type: `string`):
For advancedSearch: which posts to return. For searchVideos only hot and all apply. Default all.
## `includeType` (type: `string`):
For advancedSearch: only posts that carry this kind of media. Default all.
## `ranking` (type: `string`):
For the ranking operation: which hot list to return, about 50 entries with heat.
## `proxy` (type: `object`):
Optional proxy override. Leave empty to use the actor's built-in residential proxy. To use Apify Proxy instead, pass {"useApifyProxy": true}.
## Actor input object example
```json
{
"operation": "searchWeibo",
"weiboId": "5249718969175092",
"userId": "1669879400",
"maxPages": 5,
"fetchFullText": true,
"includeComments": false,
"maxCommentsPerPost": 20,
"keyword": "北京",
"searchType": "all",
"includeType": "all",
"ranking": "entertainment"
}
```
# Actor output Schema
## `results` (type: `string`):
No description
# API
You can run this Actor programmatically using our API. Below are code examples in JavaScript, Python, and CLI, as well as the OpenAPI specification and MCP server setup.
## JavaScript example
```javascript
import { ApifyClient } from 'apify-client';
// Initialize the ApifyClient with your Apify API token
// Replace the '' with your token
const client = new ApifyClient({
token: '',
});
// Prepare Actor input
const input = {
"weiboId": "5249718969175092",
"userId": "1669879400",
"keyword": "北京"
};
// Run the Actor and wait for it to finish
const run = await client.actor("memo23/weibo-scraper").call(input);
// Fetch and print Actor results from the run's dataset (if any)
console.log('Results from dataset');
console.log(`💾 Check your data here: https://console.apify.com/storage/datasets/${run.defaultDatasetId}`);
const { items } = await client.dataset(run.defaultDatasetId).listItems();
items.forEach((item) => {
console.dir(item);
});
// 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/js/docs
```
## Python example
```python
from apify_client import ApifyClient
# Initialize the ApifyClient with your Apify API token
# Replace '' with your token.
client = ApifyClient("")
# Prepare the Actor input
run_input = {
"weiboId": "5249718969175092",
"userId": "1669879400",
"keyword": "北京",
}
# Run the Actor and wait for it to finish
run = client.actor("memo23/weibo-scraper").call(run_input=run_input)
# Fetch and print Actor results from the run's dataset (if there are any)
print(f"💾 Check your data here: https://console.apify.com/storage/datasets/{run.default_dataset_id}")
for item in client.dataset(run.default_dataset_id).iterate_items():
print(item)
# 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/python/docs/quick-start
```
## CLI example
```bash
echo '{
"weiboId": "5249718969175092",
"userId": "1669879400",
"keyword": "北京"
}' |
apify call memo23/weibo-scraper --silent --output-dataset
```
## MCP server setup
```json
{
"mcpServers": {
"apify": {
"type": "http",
"url": "https://mcp.apify.com/?tools=fetch-actor-details,memo23/weibo-scraper"
}
}
}
```
The hosted server signs you in with OAuth on first connect, so no API token belongs in this config. Clients without OAuth support can send an `Authorization: Bearer ` header instead, using a token from API & Integrations in Apify Console (https://console.apify.com/settings/integrations).
## OpenAPI specification
Download the OpenAPI definition: https://api.apify.com/v2/actors/RU0pIbI9KSc3KBms1/builds/TS7bBhliReGsRP6gw/openapi.json