# Product Hunt \[$0.80💰] Scraper · Launches, Emails & Web Text (`memo23/producthunt-scraper`) Actor
\[Only $0.80💰] Product Hunt scraper — daily/weekly/monthly/yearly leaderboards via target selector or any URL, topics, categories, collections, products & makers. 50+ fields, launch history, website text, promoted filter, optional reviews, comments & contact emails. Pure HTTP, JSON/CSV.
- **URL**: https://apify.com/memo23/producthunt-scraper.md
- **Developed by:** [Muhamed Didovic](https://apify.com/memo23) (community)
- **Categories:** Lead generation, Automation, Agents
- **Features:** Limited permissions
- **Stats:** 341 total users, 86 monthly users, 93.6% runs succeeded, 0 bookmarks
- **User rating**: 5.00 out of 5 stars
## Pricing
from $0.80 / 1,000 results
This Actor is paid per event. You are not charged for the Apify platform usage, but only a fixed price for specific events.
Learn more: https://docs.apify.com/actors/running/actors-in-store.md#pay-per-event
## What's an Apify Actor?
An Actor is a serverless cloud program that runs on the Apify platform. It has two run modes.
In Batch mode, an Actor accepts a well-defined JSON input, performs an action which can take anything from a few seconds to a few hours,
and optionally produces a well-defined JSON output, datasets with results, or files in key-value store.
In Standby mode, an Actor provides a web server which can be used as a website, API, or an MCP server.
Apify vocabulary and the platform model are defined once, in the agent quickstart at https://apify.com/agents.md.
## How to integrate an Actor?
If asked about integration, you help developers integrate Actors into their projects.
You adapt to their stack and deliver integrations that are safe, well-documented, and production-ready.
Do not guess an integration path. Every one of them is in the agent quickstart at https://apify.com/agents.md: the Apify MCP server, Agent Skills with the Apify CLI, the JavaScript and Python clients, the REST API, and the account-free path for an agent with no human to sign in. It also carries the rule on stating cost before the first paid run.
For examples already wired to this Actor's own input schema, see the [API](#api) section below.
Each client library has reference documentation the quickstart does not restate: [JavaScript/TypeScript](https://docs.apify.com/api/client/js/docs.md) (`npm install apify-client`) and [Python](https://docs.apify.com/api/client/python/docs.md) (`pip install apify-client`).
# README
## Product Hunt Scraper — Launches, Reviews, Comments & Contact Emails
Turn any Product Hunt URL into a clean, structured dataset. Pick a source with the `target` selector — daily, weekly, monthly, yearly leaderboards, a category, a topic, or paste URLs — or start from a date range, slugs, or individual products/makers. All auto-classified from one input.
Get 50+ fields per product including votes, rank, comments, and a media gallery — plus makers and the hunter with LinkedIn, optional **detailed reviews**, **discussion threads + full comment bodies**, **full launch history**, **website text** (title, description, visible text from each product's own site), and contact emails harvested from that same site. Filter promoted listings in or out. No Product Hunt API key. Pure HTTP, no browser.
### Why Use This Scraper?
- ✅ Every Product Hunt entry point in one input — pick a source with `target` (daily / weekly / monthly / yearly / category / topic / pageUrls), or paste leaderboards, topics, categories, collections, products, and maker profiles together; each is auto-classified
- ✅ Date range (`startDate` / `endDate`) and `featuredOnly` without walking the homepage unbounded
- ✅ Weekly / monthly / yearly leaderboard ranges as first-class inputs (`startWeek`/`endWeek`, `startMonth`/`endMonth`, `startYear`/`endYear`) — no need to paste URLs
- ✅ Category and topic slugs (`categorySlugs`, `topicSlugs`) expand to the right URLs for you
- ✅ Rankings built in — vote counts, daily/weekly/monthly rank, comment counts, and the featured timestamp on every leaderboard-sourced row
- ✅ Makers + hunter on every product — name, headline, profile, follower count, LinkedIn and X. No API token
- ✅ Optional detailed reviews — full review text, five per-dimension ratings, and selected pros/cons per product
- ✅ Optional discussion threads + full comment bodies — no API token
- ✅ Optional full launch history (`launches[]`) — the product's past Product Hunt launches, parsed from the Apollo cache at no extra HTTP cost
- ✅ Optional website text (`websiteTitle`, `websiteDescription`, `websiteText`) captured from each product's own site in the same fetch used for email harvesting
- ✅ Promoted-listings filter (`includePromotedListings`) — keep or drop listings Product Hunt marks as promoted
- ✅ Contact emails harvested from each product's own website (mailto + plain-text, junk-filtered, deduped per site)
- ✅ Business fields the other scrapers skip — funding amount, employee band, YC flag, alternatives, review pro/con tags
- ✅ JSON or CSV output, ready for spreadsheets and CRMs
#### Coming from another Product Hunt scraper?
| You already get here | Often missing elsewhere |
|---|---|
| `target` source selector (daily/weekly/monthly/yearly/category/topic/pageUrls) | One flat URL list, or weekly/monthly/yearly ranges not exposed as inputs |
| Weekly / monthly / yearly leaderboard ranges (`startWeek`…`endWeek` etc.) | Paste-the-URL only, or no weekly/monthly range at all |
| `categorySlugs` / `topicSlugs` expand to URLs for you | Slug inputs not supported |
| `launches[]` — full launch history per product, no extra HTTP | Latest launch only, or a paid extra fetch |
| `websiteTitle` / `websiteDescription` / `websiteText` from each product's site | Emails only, or nothing from the product's own website |
| `includePromotedListings` filter | No promoted flag tracked at all |
| Collections + `/collections` + `/categories/{slug}` + `/search?q=` | Search-only, or no category URL |
| `startDate` / `endDate` + `featuredOnly` | Homepage walk with no date picker |
| Homepage walk-back across recent daily leaderboards | A single "today" snapshot |
| Reviews with 5 ratings, pos/neg text, selected pros/cons | Star + a text blob |
| Discussion threads (title, preview, pin, author) **and** comment bodies | Flat comments, or bodies behind a PH API key |
| `fundingAmount`, `employeeSize`, `wasInYCombinator` | Explicitly not scraped |
| `alternatives[]`, `proConTags[]` | — |
| Company emails on by default, junk-filtered | Off by default, or billed as a separate event |
| Makers + hunter + founder LinkedIn, no API key | Token required, or LinkedIn omitted |
### Overview
The Product Hunt Scraper is built for founders, marketers, VCs, and researchers who need Product Hunt data in a spreadsheet instead of a browser tab.
The output is primarily **product-shaped rows**. Even when you start from a leaderboard, topic, category, or collection URL, the resulting dataset is a stream of product rows (`rowType: "product"`) — not separate leaderboard or collection rows. The exception is a direct maker profile URL (`/@username`), which emits a single maker row (`rowType: "maker"`).
The parser reads Product Hunt's server-rendered Apollo cache (the same data the page UI uses) rather than scraping rendered HTML, so it stays resilient to PH's frequent visual redesigns. URLs are auto-classified by shape — you just paste them, you don't tag them.
### Supported Inputs
#### Source selector (`target`)
Pick a source with `target` and fill in only that source's options — no URL pasting needed:
| `target` | Fill in | Expands to |
|---|---|---|
| `daily` | `startDate` / `endDate` | `/leaderboard/daily/YYYY/M/D` |
| `weekly` | `startWeek` / `endWeek` (YYYY-WW) | `/leaderboard/weekly/YYYY/WW` |
| `monthly` | `startMonth` / `endMonth` (YYYY-MM) | `/leaderboard/monthly/YYYY/M` |
| `yearly` | `startYear` / `endYear` (YYYY) | `/leaderboard/yearly/YYYY` |
| `category` | `categorySlugs` | `/categories/{slug}` |
| `topic` | `topicSlugs` | `/topics/{slug}` (paginated) |
| `pageUrls` | `startUrls` | any mix of the URL types below |
When `target` is empty, the actor scrapes whatever you put in `startUrls` (or today's daily leaderboard if nothing else is set). You can still mix any URLs in `startUrls` regardless of `target`.
#### URL types
| URL type | Pattern | Example |
|---|---|---|
| Homepage | `producthunt.com/` | `https://www.producthunt.com/` |
| Daily leaderboard | `/leaderboard/daily/YYYY/M/D` | `https://www.producthunt.com/leaderboard/daily/2026/5/22` |
| Weekly leaderboard | `/leaderboard/weekly/YYYY/WW` | `https://www.producthunt.com/leaderboard/weekly/2026/20` |
| Monthly leaderboard | `/leaderboard/monthly/YYYY/M` | `https://www.producthunt.com/leaderboard/monthly/2026/5` |
| Yearly leaderboard | `/leaderboard/yearly/YYYY` | `https://www.producthunt.com/leaderboard/yearly/2025` |
| Topic page | `/topics/{slug}` | `https://www.producthunt.com/topics/artificial-intelligence` |
| Category page | `/categories/{slug}` | `https://www.producthunt.com/categories/ai-agents` |
| Search | `/search?q=…` | `https://www.producthunt.com/search?q=ai+agent` |
| Collection | `/collections/{slug}` | `https://www.producthunt.com/collections/best-ai-tools` |
| Collections index | `/collections` | `https://www.producthunt.com/collections` |
| Product detail | `/products/{slug}` or `/posts/{slug}` | `https://www.producthunt.com/products/bolt-new` |
| Maker profile | `/@{username}` | `https://www.producthunt.com/@ericsimons40` |
Homepage and listing URLs (leaderboards, topics, categories, collections) **fan out** to product rows and stop once `maxItems` is reached. The homepage walks recent daily leaderboards (newest first). A category URL uses the first server-rendered page (~15 products).
#### Copy-pasteable startUrls
```json
{
"startUrls": [
"https://www.producthunt.com/leaderboard/daily/2026/5/22",
"https://www.producthunt.com/leaderboard/weekly/2026/20",
"https://www.producthunt.com/topics/artificial-intelligence",
"https://www.producthunt.com/categories/ai-agents",
"https://www.producthunt.com/search?q=ai+agent",
"https://www.producthunt.com/collections/best-ai-tools",
"https://www.producthunt.com/products/bolt-new",
"https://www.producthunt.com/@ericsimons40"
]
}
```
`startUrls` accepts both plain strings (`"https://…"`) and request objects (`{ "url": "https://…" }`) — mix freely.
#### Unsupported inputs
- ❌ Content behind a Product Hunt login (private/draft launches, account settings)
- ❌ Hosts outside `producthunt.com`
### Use Cases
| Audience | Use case |
|---|---|
| **Founders & indie makers** | Track competitor launches, benchmark votes/rank, study winning taglines, reviews, and media |
| **Marketing & growth teams** | Build outreach lists from new launches with contact emails attached |
| **VCs & scouts** | Source deals from daily/weekly leaderboards; filter by funding, YC alumni, traction, review sentiment |
| **Sales / lead-gen** | Turn leaderboards + collections into a ready-to-import prospect list |
| **Researchers & analysts** | Bulk-export launches, reviews, and discussions across topics and time periods |
| **Agencies** | Deliver client-ready Product Hunt datasets without writing a scraper |
### How It Works
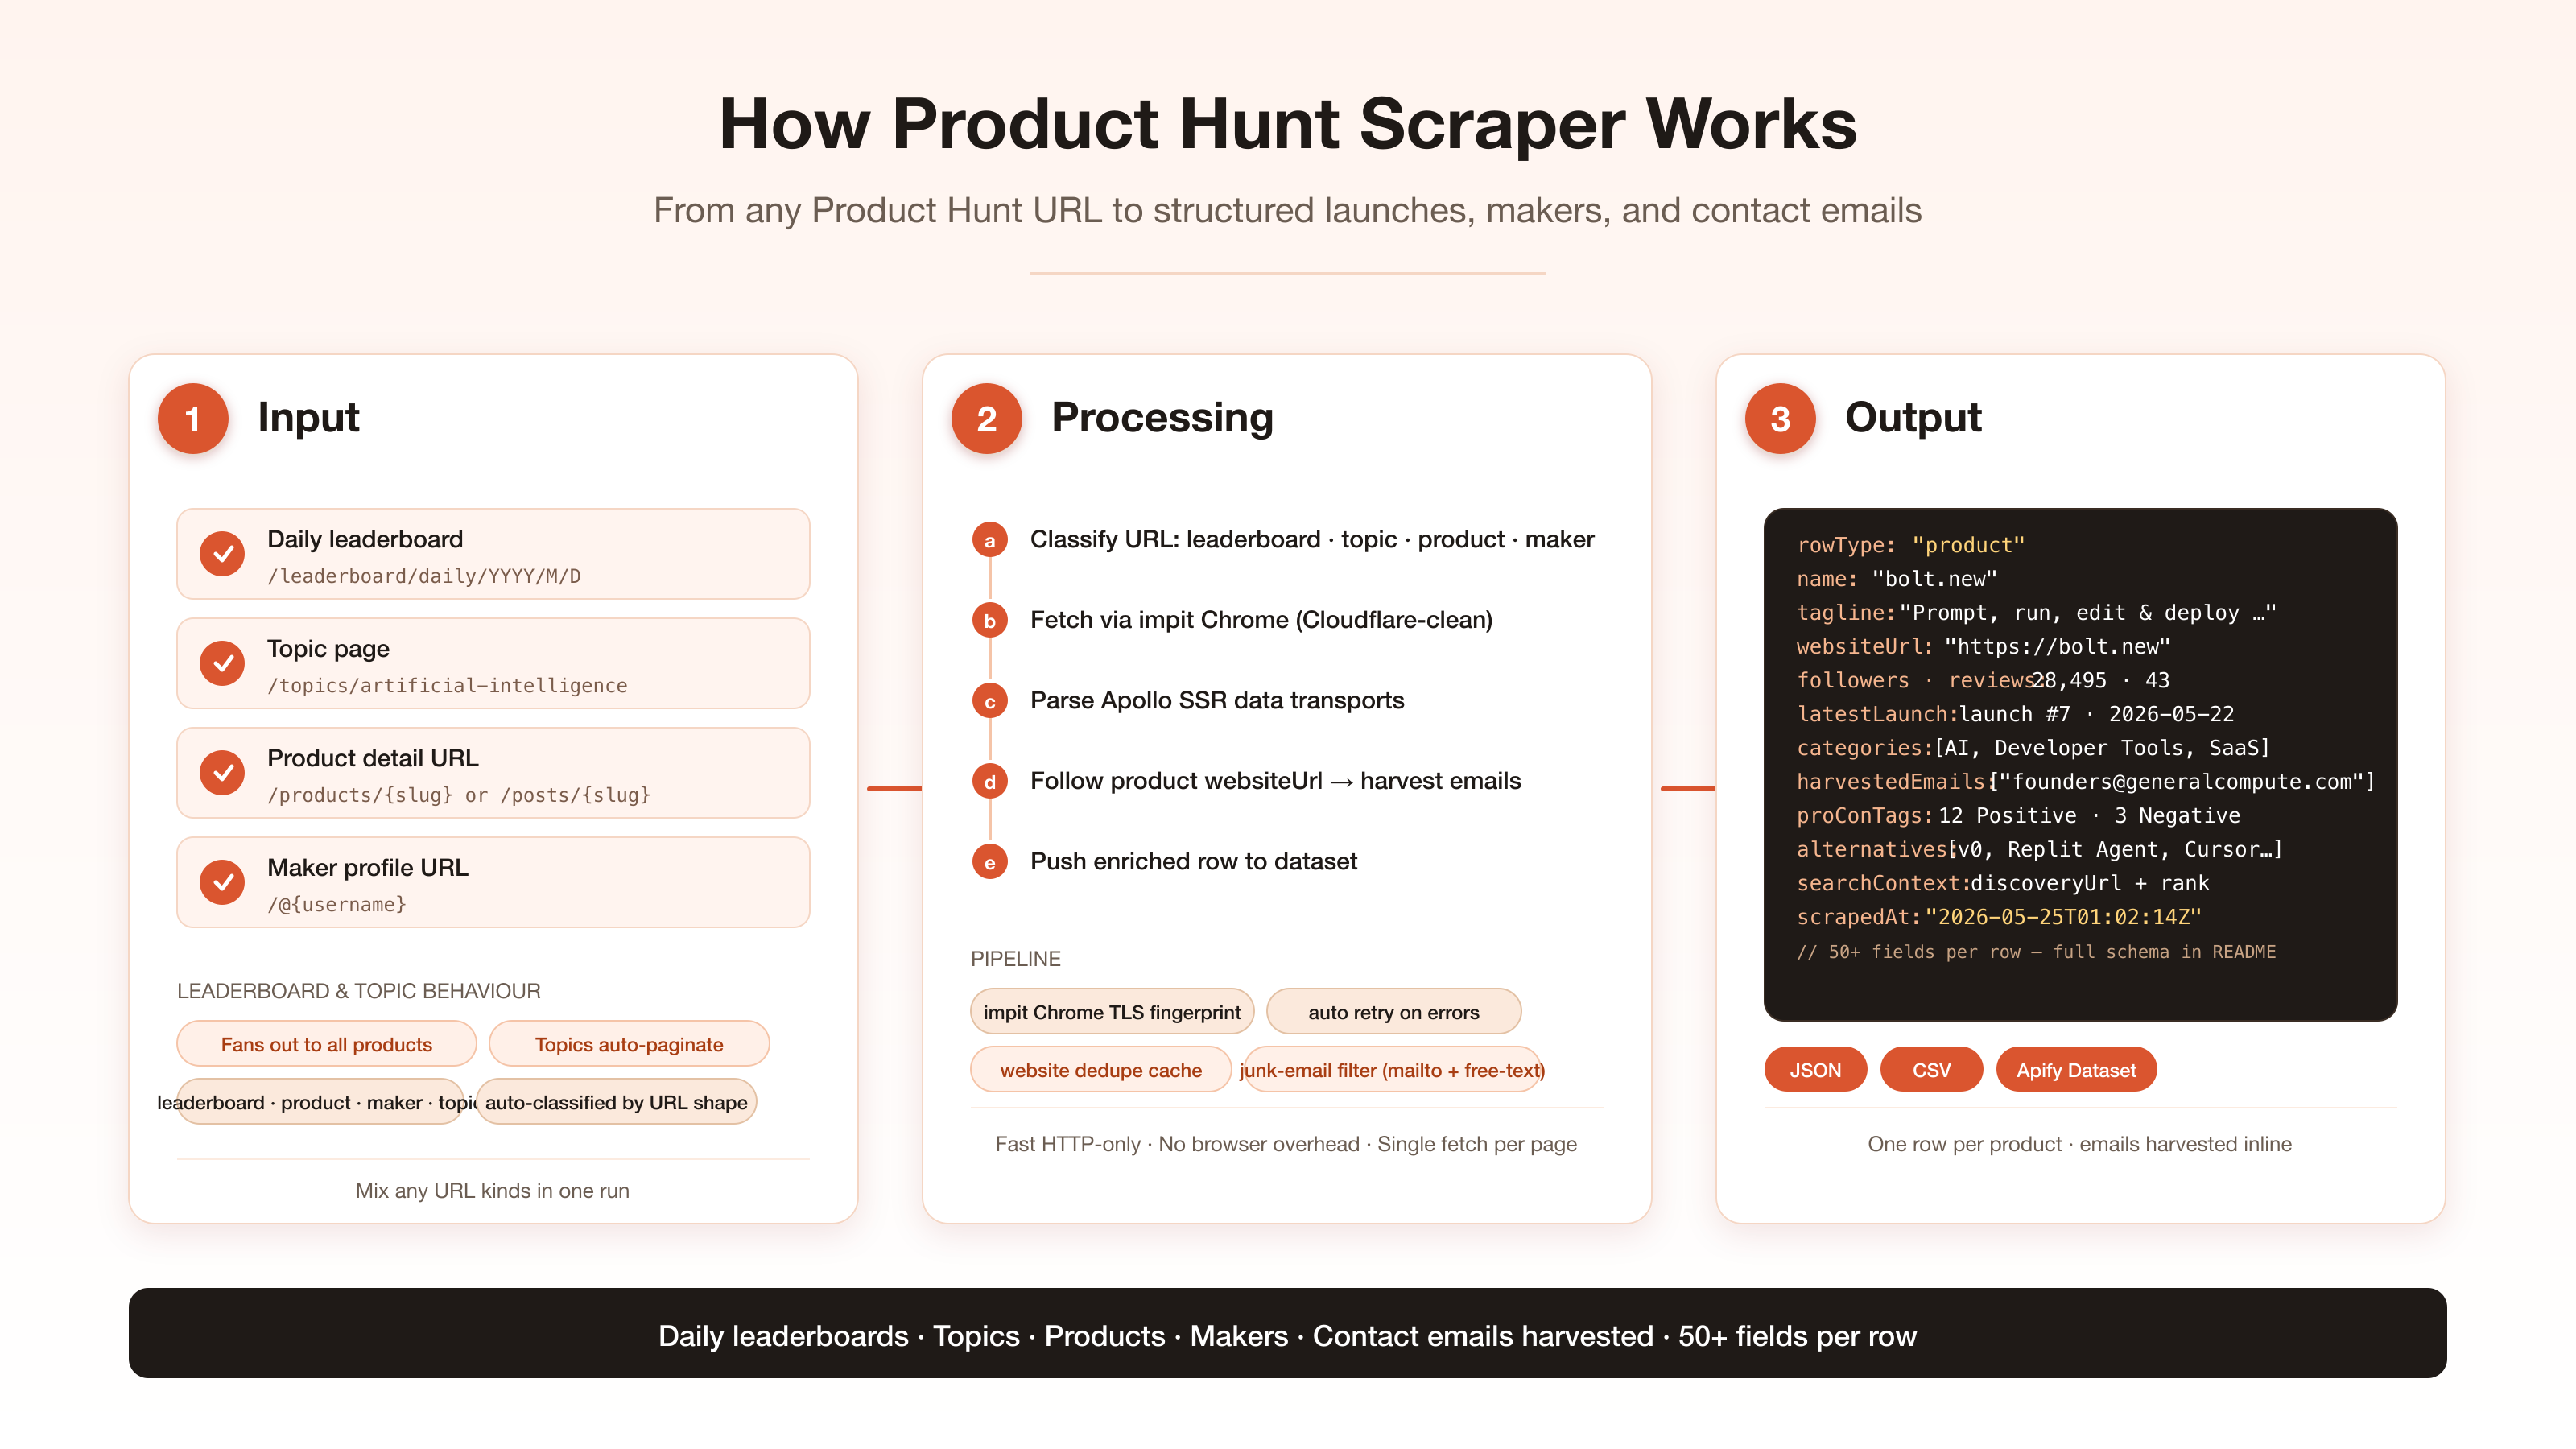
1. **Input** — paste any mix of Product Hunt URLs (homepage, leaderboards, topics, categories, collections, products, makers) and optionally a date range
2. **Auto-classify & fan out** — each URL is routed to the right handler; listing URLs expand to their products
3. **Fetch** — pages are retrieved over HTTP with a real Chrome TLS fingerprint (passes Cloudflare without a browser)
4. **Parse & enrich** — the Apollo cache is read for 50+ fields, makers, hunter, votes/rank, and the media gallery; maker profiles add LinkedIn; optionally add reviews, comment bodies, and contact emails from each product's site
5. **Output** — one product row per launch (or one maker row per `/@username`), as JSON or CSV
### Input Configuration
| Field | Type | Required | Notes |
|---|---|---|---|
| `target` | `string` | no | Source selector: `daily` / `weekly` / `monthly` / `yearly` / `category` / `topic` / `pageUrls`. Fill in only that source's options below. Empty + no other input → today's daily leaderboard. |
| `startUrls` | `array` | no | Any mix of supported Product Hunt URLs. Auto-classified. Empty + no dates → today's daily leaderboard. |
| `startDate` / `endDate` | `YYYY-MM-DD` | no | Inclusive daily-leaderboard range. One date alone = that day. Homepage + a range uses the range, not an unbounded walk-back. |
| `startWeek` / `endWeek` | `YYYY-WW` | no | Inclusive weekly-leaderboard range (e.g. `2026-22`). One week alone = that week. Use with `target: weekly`. |
| `startMonth` / `endMonth` | `YYYY-MM` | no | Inclusive monthly-leaderboard range (e.g. `2026-11`). One month alone = that month. Use with `target: monthly`. |
| `startYear` / `endYear` | `YYYY` | no | Inclusive yearly-leaderboard range (e.g. `2026`). One year alone = that year. Use with `target: yearly`. |
| `categorySlugs` | `string[]` | no | Category slugs (e.g. `ai-code-editors`), expanded to `/categories/{slug}`. Use with `target: category`. |
| `topicSlugs` | `string[]` | no | Topic slugs (e.g. `developer-tools`), expanded to `/topics/{slug}` (paginated). Use with `target: topic`. |
| `searchQueries` | `string[]` | no | Keyword searches, expanded to `/search?q=` (paginated, ~10/page). |
| `featuredOnly` | `boolean` | no | Default `false`. Skip fan-out launches with no `featuredAt`. Pasted product/maker URLs and search hits are kept. |
| `includePromotedListings` | `boolean` | no | Default `true`. Keep listings Product Hunt marks as promoted. Turn off to keep non-promoted listings only. |
| `leanMode` | `boolean` | no | Default `false`. Skip emails, website text, reviews, comments, add-ons, launch history, and maker-profile fetches. |
| `scrapeAddons` | `boolean` | no | Default `false`. Attach `builtWith[]` from `/products/{slug}/addons`. |
| `scrapeLaunches` | `boolean` | no | Default `false`. Attach `launches[]` — the product's visible Product Hunt launch history (latest + first post), parsed from the Apollo cache at no extra HTTP cost. |
| `scrapeWebsiteText` | `boolean` | no | Default `false`. Fetch each product's `websiteUrl` (same visit used for email harvesting) and attach `websiteTitle`, `websiteDescription`, `websiteText`. No extra HTTP when emails are already on. |
| `enrichMakerEmails` | `boolean` | no | Default `true`. For each product, fetch its `websiteUrl` and harvest emails (junk-filtered, capped at 10/site, deduped per URL). Each unique email found is billed as a small add-on (see Store pricing). Disable for pure PH metadata (~30% faster). |
| `scrapeReviews` | `boolean` | no | Default `false`. Attach detailed reviews per product (one extra request each). |
| `maxReviews` | `integer` | no | Default `50`. PH server-renders ~10, so higher values rarely add more. |
| `scrapeComments` | `boolean` | no | Default `false`. Attach discussion threads **and** full comment bodies from the launch page (one extra request each). No token. |
| `maxComments` | `integer` | no | Default `20`. Cap on comment bodies per launch. |
| `apiToken` | `string` (secret) | no | Unused for makers, hunter, LinkedIn, or comments. Leave blank. Fallback only if a launch page has no SSR makers/comments. |
| `maxItems` | `integer` | no | Hard cap on **total dataset rows**. Default `2000`. Free-tier runs are capped at `100`. |
| `maxConcurrency` | `integer` | no | Detail pages fetched in parallel. Default `8` (6–10 is the sweet spot). |
| `minConcurrency` | `integer` | no | Minimum parallelism. Default `1`. |
| `maxRequestRetries` | `integer` | no | Per-URL retry budget. Soft-blocks/thin bodies auto-retried with a fresh session. Default `5`. |
| `proxy` | `object` | no | Defaults to Apify Proxy. Supply your own residential pool for geo-locked output or heavy runs. |
#### Common scenarios
**1. A day's launches with contact emails**
```json
{
"startUrls": ["https://www.producthunt.com/leaderboard/daily/2026/5/22"],
"enrichMakerEmails": true
}
```
**2. Launches with reviews and discussion threads**
```json
{
"startUrls": ["https://www.producthunt.com/products/bolt-new"],
"scrapeReviews": true,
"scrapeComments": true
}
```
**3. Full enrichment — emails + makers + hunter + comment bodies**
```json
{
"startUrls": ["https://www.producthunt.com/leaderboard/weekly/2026/20"],
"enrichMakerEmails": true,
"scrapeComments": true
}
```
**4. A date range, featured launches only**
```json
{
"startDate": "2026-09-01",
"endDate": "2026-09-07",
"featuredOnly": true,
"maxItems": 200
}
```
**5. A weekly leaderboard range via the `target` selector**
```json
{
"target": "weekly",
"startWeek": "2026-20",
"endWeek": "2026-22"
}
```
**6. A category by slug, with launch history + website text**
```json
{
"target": "category",
"categorySlugs": ["ai-code-editors"],
"scrapeLaunches": true,
"scrapeWebsiteText": true
}
```
Makers, hunter, LinkedIn, and comment bodies come from the pages themselves. No Product Hunt developer token.
### Output Overview
Each dataset item is one of two shapes, set by `rowType`:
- **`product`** — emitted for every product (from leaderboards, topics, collections, the homepage, or direct product URLs). Carries the full 50+ field schema, plus `reviews[]`, `discussionThreads[]`, and `comments[]` when enabled.
- **`maker`** — emitted only for a direct `/@username` URL. Profile + the maker's launched products.
Notes on when fields are populated:
- **Votes, rank, comments count, `featuredAt`** are present on rows discovered via a leaderboard/topic/category/collection. They're `null` on a direct `/products/{slug}` URL (no ranking context).
- **`reviews[]`** appears only with `scrapeReviews`; **`discussionThreads[]`** and **`comments[]`** only with `scrapeComments`.
- **`makersEnriched` + `hunter`** (including LinkedIn when the maker published one) are on every product row. **`harvestedEmails`** requires `enrichMakerEmails` and a site that exposes an email.
Output is nested JSON by default; the Apify Console "Export" tab flattens it to CSV.
### Output Samples
#### Product row — leaderboard-discovered, with reviews + threads
```jsonc
{
"rowType": "product",
"slug": "bolt-new",
"name": "bolt.new",
"tagline": "Prompt, run, edit & deploy full-stack web apps",
"websiteUrl": "https://bolt.new",
"votesCount": 661, "dailyRank": 1, "weeklyRank": 1, "commentsCount": 75,
"featuredAt": "2026-05-15T00:01:00-07:00",
"isPromoted": null,
"reviewsCount": 44, "reviewsRating": 4.7, "followersCount": 30226,
"wasInYCombinator": false,
"harvestedEmails": ["hello@stackblitz.com"],
"websiteTitle": "Bolt AI builder: Websites, apps & prototypes",
"websiteDescription": "Build and scale high-performing websites & apps using your words.",
"websiteText": "Bolt AI builder: Websites, apps & prototypes Back Solutions Resources…",
"launches": [
{ "id": "1252832", "slug": "bolt-new", "name": "Bolt Forge", "launchState": "featured", "launchedThisWeek": true, "createdAt": "2026-05-15T00:01:00-07:00" }
],
"reviews": [
{
"id": "535045", "overallRating": 4, "easeOfUseRating": 4, "valueForMoneyRating": 4,
"overallExperience": null,
"positiveFeedback": "bolt.new runs the whole thing in the browser, so you go from prompt to a running app with no local setup…",
"negativeFeedback": null,
"selectedPros": ["Fast prototyping", "No setup"], "selectedCons": ["Token usage"],
"votesCount": 3, "createdAt": "2026-05-20T10:11:00-07:00",
"reviewer": { "name": "Jane D.", "username": "janed", "isVerified": true }
}
/* … up to ~10 reviews … */
],
"discussionThreads": [
{
"id": "717330", "title": "AMA w/ CEO of Bolt — from $0 to $20M",
"descriptionPreview": "Live Feb 28th, 9am PT — drop your questions!",
"commentsCount": 28, "isPinned": false, "createdAt": "2026-02-26T08:00:00-08:00",
"author": { "username": "ericsimons40", "name": "Eric Simons" }
}
],
"comments": [
{ "id": "5816849", "body": "Hey Product Hunt! Safi here from the team…", "votesCount": 32, "author": { "username": "safi_amin" } }
],
"makersEnriched": [
{ "name": "Safi Amin", "username": "safi_amin", "headline": "PM at SandboxAQ", "linkedinUrl": "https://www.linkedin.com/in/safiamin", "followersCount": 16 }
],
"hunter": { "name": "fmerian", "username": "fmerian", "profileUrl": "https://www.producthunt.com/@fmerian" },
"scrapedAt": "2026-06-14T11:42:00.000Z"
/* plus githubUrl/twitterUrl/etc., media[], categories[], proConTags[],
business fields, latestLaunch, searchContext, and `raw` (full Apollo block) */
}
```
#### Maker row — direct `/@username`
```jsonc
{
"rowType": "maker",
"sourceUrl": "https://www.producthunt.com/@ericsimons40",
"username": "ericsimons40",
"name": "Eric Simons",
"headline": "CEO @StackBlitz",
"twitterUsername": "ericsimons40",
"twitterUrl": "https://x.com/ericsimons40",
"linkedinUrl": null,
"links": [{ "kind": "twitter", "name": "Twitter", "url": "https://twitter.com/ericsimons40" }],
"productsCount": 8,
"followersCount": 1944,
"followingCount": 2,
"products": [ { "id": "599447", "name": "bolt.new" } ],
"scrapedAt": "2026-06-14T11:42:00.000Z"
}
```
### Key Output Fields
#### Identity & links
- `rowType`, `productId`, `slug`, `name`, `tagline`, `description`, `sourceUrl`, `canonicalUrl`
- `websiteUrl`, `githubUrl`, `iosUrl`, `androidUrl`, `twitterUrl`, `linkedinUrl`, `facebookUrl`, `instagramUrl`
#### Ranking, engagement & media
- `votesCount`, `launchDayScore`, `dailyRank`, `weeklyRank`, `monthlyRank`, `commentsCount`, `featuredAt`, `isPromoted`
- `reviewsCount`, `reviewsRating`, `followersCount`
- `media[]` — `mediaType` (`image`/`video`), `imageUuid`, `width`, `height`, `videoId`
#### Business, categories & sentiment
- `employeeSize`, `fundingAmount`, `wasInYCombinator`, `isTopProduct`, `isNoLongerOnline`
- `categories[]`, `latestLaunch`, `firstPost`, `launches[]` (with `scrapeLaunches`), `alternatives[]`, `proConTags[]`, `builtWith[]` (with `scrapeAddons`)
#### Reviews (with `scrapeReviews`)
- `reviews[].overallRating`, `.easeOfUseRating`, `.reliabilityRating`, `.valueForMoneyRating`, `.customizationRating`
- `reviews[].overallExperience`, `.positiveFeedback`, `.negativeFeedback`, `.selectedPros`, `.selectedCons`, `.votesCount`, `.reviewer`
#### Discussion & comments (with `scrapeComments`)
- `discussionThreads[].title`, `.descriptionPreview`, `.commentsCount`, `.isPinned`, `.author`
- `comments[].body`, `.votesCount`, `.url`, `.author`
#### People
- `makersEnriched[]` / `hunter` — `name`, `username`, `headline`, `profileUrl`, `followersCount`, `linkedinUrl`, `twitterUrl`, `links[]`
- Maker rows also carry `followingCount`, `linkedinUrl`, `links[]`
#### Enrichment (optional)
- `harvestedEmails[]` (with `enrichMakerEmails`)
- `websiteTitle`, `websiteDescription`, `websiteText` (with `scrapeWebsiteText`)
#### Discovery context
- `searchContext.discoveryUrl`, `.resultPosition`, `.leaderboardDate`, `.topicSlug`, `.collectionSlug`
### FAQ
#### Which Product Hunt URLs are supported?
Homepage, daily/weekly/monthly/yearly leaderboards, a `startDate`/`endDate` range, topics, `/categories/{slug}` (first SSR page), `/search?q=` (or `searchQueries`), collections (and the `/collections` index), product detail (`/products/{slug}` or `/posts/{slug}`), and maker profiles (`/@username`). Mix any of them in `startUrls`.
#### Do I get product rows or leaderboard/collection rows?
Product rows. Leaderboards, topics, categories, collections, and the homepage all **fan out** to product rows (`rowType: "product"`). Only a direct `/@username` URL produces a maker row.
#### What do `scrapeReviews` and `scrapeComments` add?
`scrapeReviews` attaches a `reviews[]` array (full text, five ratings, pros/cons, reviewer). `scrapeComments` attaches `discussionThreads[]` and full `comments[]` bodies from the launch page. Each adds one HTTP request per product and is off by default.
#### Do I need a Product Hunt API token?
No. Makers, hunter, LinkedIn, reviews, and comment bodies are read from public Product Hunt pages. `apiToken` is an unused fallback — leave it blank.
#### How do I get makers and the hunter?
They are on every product row (`makersEnriched[]`, `hunter`). LinkedIn is filled when the maker published one on their Product Hunt profile.
#### Can I search by keyword?
Yes. Paste `https://www.producthunt.com/search?q=ai+agent` or set `searchQueries: ["ai agent"]`. Results are in the page HTML (`productSearch`, ~10 per `?page=`).
#### How do I scrape a date range?
Set `startDate` and `endDate` (YYYY-MM-DD). The actor expands them into daily leaderboards. One date alone scrapes that day. You can also paste other URLs in the same run. A homepage URL plus a range uses the range, not an unbounded walk-back. For weekly/monthly/yearly ranges, use `target: weekly`/`monthly`/`yearly` with `startWeek`/`endWeek`, `startMonth`/`endMonth`, or `startYear`/`endYear`.
#### What does `target` do?
`target` picks a source so you don't have to paste URLs. Set `target: weekly` + `startWeek`/`endWeek`, or `target: category` + `categorySlugs`, etc. When `target` is empty, the actor scrapes whatever you put in `startUrls` (or today's daily leaderboard if nothing else is set).
#### What do `scrapeLaunches` and `scrapeWebsiteText` add?
`scrapeLaunches` attaches `launches[]` — the product's visible Product Hunt launch history (latest + first post), parsed from the Apollo cache at no extra HTTP cost. `scrapeWebsiteText` fetches each product's own website (the same visit used for email harvesting) and attaches `websiteTitle`, `websiteDescription`, and `websiteText`. Both are off by default.
#### What does `includePromotedListings` do?
When `false`, fan-out skips listings Product Hunt marks as promoted. Default `true` (keep everything). The `isPromoted` flag is on every product row either way.
#### What does `featuredOnly` do?
When `true`, listing fan-out (leaderboard / topic / category / collection) skips launches with an empty `featuredAt`. Product and maker URLs you paste yourself are always kept.
#### Why are `votesCount` / `dailyRank` sometimes null?
Those come from a leaderboard/topic/category/collection's ranking data. A direct `/products/{slug}` URL has no ranking context, so they're `null`. Reach a product via a leaderboard to get them.
#### Some products have `harvestedEmails: []` — why?
Email harvesting is best-effort. A site may not publish an email, may load it via JavaScript, or may obfuscate it. Realistic harvest rate is roughly 30–50% of product sites.
#### Can I scrape private or login-gated content?
No. The actor only reads publicly available pages. Anything behind a Product Hunt login is out of scope.
#### What about rate limits?
The scraper runs cleanly at `maxConcurrency=8`; lower it or add a residential proxy if you see soft-blocks. Maker-profile fetches (for LinkedIn) are cached per username for the run.
### Support
Found a bug, hit a soft-block we don't detect, or want another URL kind supported? Open an issue on the actor's **Issues** tab, or reach out via the [memo23 profile](https://apify.com/memo23) on Apify.
### Additional Services
Need a custom export shape, a new entry point, or scheduled monitoring? I build tailored scrapers and enrichment pipelines — get in touch via the [memo23 profile](https://apify.com/memo23).
### Explore More Scrapers
If you track Product Hunt launches, founders, and prospects, these pair well:
- [**Y Combinator Scraper**](https://apify.com/memo23/y-combinator-scraper) — companies + jobs from YC; cross-reference the `wasInYCombinator` flag
- [**G2 Scraper**](https://apify.com/memo23/g2-scraper) — see how a launched SaaS ranks on G2 reviews
- [**Trustpilot Scraper**](https://apify.com/memo23/trustpilot-scraper-ppe) — customer sentiment for products you discover
- [**LinkedIn Profiles Scraper**](https://apify.com/memo23/linkedin-profile-scraper) — backfill founder profiles for makers
- [**PagesJaunes Leads Scraper**](https://apify.com/memo23/pagesjaunes-scraper-cheerio) — bulk B2B leads with emails
Full portfolio: [apify.com/memo23](https://apify.com/memo23).
***
### 🤖 For AI Agents & LLM Apps
Compact reference for AI agents calling this actor via the [Apify MCP server](https://mcp.apify.com) or the Apify API (actor: `memo23/producthunt-scraper`).
**Purpose:** Turn any Product Hunt URL (leaderboards, date range, topics, categories, collections, products, maker profiles) into structured product rows read from PH's server-rendered Apollo cache, with optional reviews, discussion threads, and contact emails.
**Minimal input:**
```json
{
"startUrls": ["https://www.producthunt.com/leaderboard/daily/2026/5/22"],
"maxItems": 20
}
```
**Output:** one row per product (`rowType: "product"`) with slug, name, tagline, websiteUrl, votesCount, dailyRank, weeklyRank, monthlyRank, commentsCount, featuredAt, isPromoted, reviewsCount, reviewsRating, followersCount, wasInYCombinator, media\[], categories\[], harvestedEmails\[], and (when enabled) websiteTitle, websiteDescription, websiteText, launches\[], reviews\[], discussionThreads\[], comments\[], makersEnriched\[], hunter, searchContext, scrapedAt. A direct `/@username` URL emits one maker row (`rowType: "maker"`) with username, name, headline, productsCount, followersCount, products\[].
**Behaviors an agent should know:**
- Always set `maxItems` (default 2000): a topic page can fan out to hundreds of products; a single daily leaderboard yields ~17-30. Free-tier runs cap at 100.
- `target` selects a source (`daily`/`weekly`/`monthly`/`yearly`/`category`/`topic`/`pageUrls`); fill in only that source's options (`startWeek`/`endWeek`, `startMonth`/`endMonth`, `startYear`/`endYear`, `categorySlugs`, `topicSlugs`, or `startUrls`). Empty + no other input → today's daily leaderboard.
- `startUrls` are auto-classified; leaderboards/topics/categories/collections/homepage fan out to product rows, `/products/{slug}` emits one product, `/@username` emits one maker row.
- `startDate`/`endDate` expand to daily leaderboards. `featuredOnly` drops unfeatured listing rows; pasted product/maker URLs stay. `includePromotedListings` (default true) drops promoted listings when false.
- `scrapeLaunches` attaches `launches[]` (latest + first post, no extra HTTP). `scrapeWebsiteText` attaches `websiteTitle`/`websiteDescription`/`websiteText` from the same fetch used for emails. `scrapeReviews` and `scrapeComments` are off by default and each add one request per product. `makersEnriched` / `hunter` (with LinkedIn when published) are always populated from the page — no `apiToken`.
- `votesCount`/`dailyRank` are null on direct product URLs (no ranking context); reach a product via a leaderboard to populate them.
- Pay-per-event billing — see the Pricing tab on the actor page. The optional email enrichment (`enrichEmails`) is charged only per contact email found, never for misses.
***
### ⚠️ Disclaimer
This Actor is an independent tool and is not affiliated with, endorsed by, or sponsored by Product Hunt or any of its parent companies or subsidiaries. All trademarks mentioned are the property of their respective owners.
The scraper accesses only publicly available Product Hunt pages — no authenticated endpoints, private launches, or content behind the producthunt.com login wall. Users are responsible for ensuring their use complies with Product Hunt's Terms of Service, applicable data-protection law (GDPR, CCPA, etc.), and any contractual obligations of their own organization. Harvested contact emails and founder profile links are personal data — process them responsibly, honor opt-outs, and seek legal advice before outbound marketing.
***
### SEO Keywords
product hunt scraper, scrape product hunt, producthunt scraper, product hunt api, product hunt.com scraper, Apify product hunt, product hunt leaderboard scraper, product hunt topic scraper, product hunt collections scraper, product hunt reviews scraper, product hunt comments scraper, maker profile scraper, product launch scraper, product hunt maker emails, founder contact scraper, saas launch tracker, b2b lead generation data, vc deal sourcing, ai product tracker, startup launch intelligence
# Actor input Schema
## `target` (type: `string`):
Choose one Product Hunt source. Fill in only that source's options below. When left empty, the actor scrapes whatever you pass in Product Hunt URLs / search queries / date range (today's daily leaderboard if nothing else is set). The `Product Hunt page URLs` choice uses the Product Hunt URLs field above.
## `startUrls` (type: `array`):
Full producthunt.com URLs to crawl. Leaderboard, topic, category, and collection URLs fan out automatically until `Maximum items to scrape` is reached. Leave empty and set a date/week/month/year range below to scrape a range. Used by the `Product Hunt page URLs` source choice.
## `startDate` (type: `string`):
Inclusive start of a daily-leaderboard range (YYYY-MM-DD, Product Hunt calendar day). Leave empty to skip. If you set this and leave End date empty, only this day is scraped. Combined with startUrls — a homepage URL plus a range uses the range instead of walking back unbounded.
## `endDate` (type: `string`):
Inclusive end of the daily-leaderboard range. Defaults to Start date when empty.
## `startWeek` (type: `string`):
First Product Hunt leaderboard week in YYYY-WW, such as 2026-22. Add an end week for an inclusive range. Used with the Weekly leaderboard source choice.
## `endWeek` (type: `string`):
Optional last week in an inclusive range, in YYYY-WW. Leave empty to scrape only the start week.
## `startMonth` (type: `string`):
First Product Hunt leaderboard month in YYYY-MM, such as 2026-11. Add an end month for an inclusive range.
## `endMonth` (type: `string`):
Optional last month in an inclusive range, in YYYY-MM. Leave empty to scrape only the start month.
## `startYear` (type: `integer`):
First Product Hunt leaderboard year, such as 2026. Add an end year for an inclusive range.
## `endYear` (type: `integer`):
Optional last year in an inclusive range. Leave empty to scrape only the start year.
## `categorySlugs` (type: `array`):
One Product Hunt category slug per row, such as ai-code-editors. Expanded to /categories/{slug} URLs.
## `topicSlugs` (type: `array`):
One Product Hunt topic slug per row, such as developer-tools or open-source. Expanded to /topics/{slug} URLs (paginated).
## `searchQueries` (type: `array`):
Keyword searches, expanded to /search?q= URLs. Same as pasting those URLs in Product Hunt URLs. Paginated (~10 products per page) until maxItems.
## `featuredOnly` (type: `boolean`):
When enabled, leaderboard / topic / category / collection fan-out skips launches with no featured timestamp. Direct product and maker URLs you paste are always kept. Search hits are kept (they usually have no featured timestamp). Default off.
## `includePromotedListings` (type: `boolean`):
Include listings that Product Hunt marks as promoted. Turn this off to keep non-promoted listings only. Default on.
## `leanMode` (type: `boolean`):
Skip every extra HTTP hop: website emails + text, reviews, comments, add-ons, launch history, and /@username profile fetches (LinkedIn overlay). SSR makers/hunter on the launch page still emit. Fastest / cheapest run.
## `scrapeAddons` (type: `boolean`):
When enabled, each product's /addons page is fetched and attached as builtWith\[] — the products listed in that product's ecosystem. PH retired the old Built-with stack tab; this is the list that remains. One extra HTTP per product. Default off.
## `scrapeLaunches` (type: `boolean`):
Collect the product's visible Product Hunt launch history and attach it as a launches\[] array. Product Hunt does not server-render the full launch list on the product page (only latestLaunch + firstPost), so this array contains the launches PH exposes there — the latest launch, and the first post when different. No extra HTTP. Default off.
## `scrapeWebsiteText` (type: `boolean`):
When enabled, each product's websiteUrl is fetched (the same visit used for email harvesting) and the page title, meta description, and a snippet of visible text are attached as websiteTitle, websiteDescription, websiteText. No extra HTTP when email harvesting is already on; one extra HTTP per unique website when it is off. Default off.
## `enrichMakerEmails` (type: `boolean`):
When enabled (default), each parsed product's `websiteUrl` is fetched and emails are extracted (mailto: links + plain-text patterns, junk filtered). Cached per URL — products sharing the same website (e.g. multiple launches of the same SaaS) are only fetched once. Adds ~0.3-1 s per unique website. Disable to ship pure Product Hunt metadata ~30% faster.
Note: Product Hunt does not expose personal websites for makers, so this enrichment harvests from product sites — not personal sites. Maker profile URLs (/@username) emit profile rows without email harvest.
## `enrichEmails` (type: `boolean`):
If enabled, finds a contact email for each result from its own website (or by discovering it from the name). Adds contactEmail + contactWebsite columns plus a detailed emailEnrichment object. Billed per contact email found; only charged when an email is returned, never for misses.
## `scrapeReviews` (type: `boolean`):
When enabled, each product's reviews page is fetched and the detailed reviews are attached to the product row: full review text (`overallExperience`), positive/negative feedback, per-dimension ratings (ease of use, reliability, value, customization), selected pros/cons, author, and vote count. Adds one HTTP request per product. Product Hunt server-renders the first ~10 reviews. Default off.
## `maxReviews` (type: `integer`):
Upper bound on reviews attached per product. PH server-renders only the first page (~10), so higher values have no effect unless PH changes that. Used only when `Scrape product reviews` is on.
## `scrapeComments` (type: `boolean`):
When enabled, the launch page is fetched and both discussion-thread metadata and full comment bodies (text, author, votes) are attached. One extra HTTP per product. No API token. Default off.
## `maxComments` (type: `integer`):
Upper bound on comment bodies attached per launch. Used only when `Scrape launch comments` is on.
## `apiToken` (type: `string`):
Optional. Makers, hunter, LinkedIn, reviews, and comment bodies are read from Product Hunt pages — no token needed. Leave blank. Only used as a fallback if a launch page has no makers or comment bodies in its HTML.
## `maxItems` (type: `integer`):
Hard cap on the number of products + makers collected. A single daily leaderboard typically yields 17-30 products; a topic page can yield hundreds across paginated pages.
## `maxConcurrency` (type: `integer`):
Maximum number of detail pages processed in parallel. Higher = faster but more bandwidth. Product Hunt's anti-bot is forgiving; 6-10 is the sweet spot.
## `minConcurrency` (type: `integer`):
Minimum number of detail pages processed in parallel.
## `maxRequestRetries` (type: `integer`):
Number of retries before a failed request is given up. Transient errors (Cloudflare soft-blocks, thin bodies) are auto-detected and retried with a fresh proxy session; this counter covers other failures too.
## `proxy` (type: `object`):
Leave empty — the actor already routes all traffic through its own built-in residential proxy at no extra cost to you. Only set this if you want to use your own proxies.
## Actor input object example
```json
{
"target": "daily",
"startUrls": [
"https://www.producthunt.com/leaderboard/daily/2026/5/22",
"https://www.producthunt.com/topics/artificial-intelligence",
"https://www.producthunt.com/categories/ai-agents",
"https://www.producthunt.com/search?q=ai+agent",
"https://www.producthunt.com/products/bolt-new",
"https://www.producthunt.com/@ericsimons40"
],
"startWeek": "2026-22",
"startMonth": "2026-11",
"startYear": 2026,
"categorySlugs": [
"ai-code-editors"
],
"topicSlugs": [
"developer-tools"
],
"featuredOnly": false,
"includePromotedListings": true,
"leanMode": false,
"scrapeAddons": false,
"scrapeLaunches": false,
"scrapeWebsiteText": false,
"enrichMakerEmails": true,
"enrichEmails": false,
"scrapeReviews": false,
"maxReviews": 50,
"scrapeComments": false,
"maxComments": 20,
"maxItems": 2000,
"maxConcurrency": 8,
"minConcurrency": 1,
"maxRequestRetries": 5
}
```
# Actor output Schema
## `results` (type: `string`):
No description
# API
You can run this Actor programmatically using our API. Below are code examples in JavaScript, Python, and CLI, as well as the OpenAPI specification and MCP server setup.
## JavaScript example
```javascript
import { ApifyClient } from 'apify-client';
// Initialize the ApifyClient with your Apify API token
// Replace the '' with your token
const client = new ApifyClient({
token: '',
});
// Prepare Actor input
const input = {
"target": "daily",
"startUrls": [
"https://www.producthunt.com/leaderboard/daily/2026/5/22",
"https://www.producthunt.com/topics/artificial-intelligence",
"https://www.producthunt.com/categories/ai-agents",
"https://www.producthunt.com/search?q=ai+agent",
"https://www.producthunt.com/products/bolt-new",
"https://www.producthunt.com/@ericsimons40"
]
};
// Run the Actor and wait for it to finish
const run = await client.actor("memo23/producthunt-scraper").call(input);
// Fetch and print Actor results from the run's dataset (if any)
console.log('Results from dataset');
console.log(`💾 Check your data here: https://console.apify.com/storage/datasets/${run.defaultDatasetId}`);
const { items } = await client.dataset(run.defaultDatasetId).listItems();
items.forEach((item) => {
console.dir(item);
});
// 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/js/docs
```
## Python example
```python
from apify_client import ApifyClient
# Initialize the ApifyClient with your Apify API token
# Replace '' with your token.
client = ApifyClient("")
# Prepare the Actor input
run_input = {
"target": "daily",
"startUrls": [
"https://www.producthunt.com/leaderboard/daily/2026/5/22",
"https://www.producthunt.com/topics/artificial-intelligence",
"https://www.producthunt.com/categories/ai-agents",
"https://www.producthunt.com/search?q=ai+agent",
"https://www.producthunt.com/products/bolt-new",
"https://www.producthunt.com/@ericsimons40",
],
}
# Run the Actor and wait for it to finish
run = client.actor("memo23/producthunt-scraper").call(run_input=run_input)
# Fetch and print Actor results from the run's dataset (if there are any)
print(f"💾 Check your data here: https://console.apify.com/storage/datasets/{run.default_dataset_id}")
for item in client.dataset(run.default_dataset_id).iterate_items():
print(item)
# 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/python/docs/quick-start
```
## CLI example
```bash
echo '{
"target": "daily",
"startUrls": [
"https://www.producthunt.com/leaderboard/daily/2026/5/22",
"https://www.producthunt.com/topics/artificial-intelligence",
"https://www.producthunt.com/categories/ai-agents",
"https://www.producthunt.com/search?q=ai+agent",
"https://www.producthunt.com/products/bolt-new",
"https://www.producthunt.com/@ericsimons40"
]
}' |
apify call memo23/producthunt-scraper --silent --output-dataset
```
## MCP server setup
```json
{
"mcpServers": {
"apify": {
"type": "http",
"url": "https://mcp.apify.com/?tools=fetch-actor-details,memo23/producthunt-scraper"
}
}
}
```
The hosted server signs you in with OAuth on first connect, so no API token belongs in this config. Clients without OAuth support can send an `Authorization: Bearer ` header instead, using a token from API & Integrations in Apify Console (https://console.apify.com/settings/integrations).
## OpenAPI specification
Download the OpenAPI definition: https://api.apify.com/v2/actors/S658DEDCsHPBZSlGa/builds/zuw10mP5kDegQisBO/openapi.json